Vulkan Series: 06 - Rotating Cube
Leaving the flat world behind with uniform buffers, model, view and projection matrices, and a depth buffer in Vulkan 1.3
What we’ll build here
Our textured quad has grown up into a 3D cube, spinning away in front of a camera! And as a bonus, it’s no longer stretched when the window isn’t square.
To get here, we’ll:
- Teach our
Bufferclass about uniform buffers - Try one out with a simple colour overlay, to make sure everything’s wired up
- Learn the theory behind transformations: model, view and projection matrices
- Move our quad around with a model matrix
- Give it some perspective with a projection matrix (which finally fixes our stretched aspect ratio)
- Place a camera with a view matrix
- Correct for the difference between GLM’s and Vulkan’s idea of which way is up
- Set our quad rotating
- See why we need a depth buffer, and then create and use one
- Turn our quad into a cube
This post builds directly on top of the previous post, where we set up our Image and ShaderDataTable classes, so if you haven’t gone through that one yet, I’d strongly recommend doing so first.
Just want the source code? Find it on GitHub or at the end of this post.
Setup
Nothing new to install, and no new source files this time! We’ve had GLM since the VMA, GLM and refactoring post, and this is where it really starts earning its keep.
THEORY: Uniform buffers
So far, the only data our shaders have received from us is per-vertex data (positions, colours and texture coordinates, through our vertex buffer), and a texture. But a lot of data is the same for every vertex in a draw, like where our object is, or where the camera is looking from. Putting copies of it into every vertex would be wasteful, and we’d have to rewrite the whole vertex buffer every time it changes.
That’s what uniform buffers are for. A uniform buffer is just a buffer, like our vertex and index buffers, but our shaders read it through a descriptor, the same way they read our texture. Every invocation of the shader sees the same (“uniform”) values.
Two things make them a bit different from our vertex and index buffers:
- We write to them from the CPU, often. Our vertex data is uploaded once, through a staging buffer, into fast GPU-only memory. Uniform data, on the other hand, may change every frame, and it’s usually small. So instead of going through the staging buffer every time, we put uniform buffers in memory the CPU can write to directly.
- Their layout has rules. In the shader, a uniform buffer is declared as a block, like a struct, and the GPU expects its members at specific offsets. We’ll use the
std140layout, which has well-defined rules for this. Our C++ struct has to match them, byte for byte.
Uniform buffers in our Buffer class
Let’s add a new usage to Buffer::EUsage, in buffer.hpp:
    enum class EUsage
    {
        VERTEX,
        INDEX,
        UNIFORM,
        STAGING,
    };
And a new case to the switch in Buffer::create:
    case EUsage::UNIFORM:
      // uniform buffer
      _usage = VK_BUFFER_USAGE_UNIFORM_BUFFER_BIT;

      // allow writing to this buffer from CPU memory
      _mem_flags = VMA_ALLOCATION_CREATE_HOST_ACCESS_SEQUENTIAL_WRITE_BIT;
      break;
It’s the same as our staging buffer, apart from the usage flag. VK_BUFFER_USAGE_UNIFORM_BUFFER_BIT lets us use the buffer as a uniform buffer, and VMA_ALLOCATION_CREATE_HOST_ACCESS_SEQUENTIAL_WRITE_BIT tells VMA we want to write to it from the CPU, which makes it pick memory the CPU can actually reach. No TRANSFER_DST this time, as we won’t be copying into it on the GPU.
A uniform buffer isn’t bound like a vertex or index buffer (it goes through a descriptor instead), so bind treats it like a staging buffer:
    // we shouldn't call bind on a staging or uniform buffer
    case EUsage::UNIFORM:
    case EUsage::STAGING:
      assert(false);
    break;
And since we’ll be writing to it directly, copy_from_cpu now accepts uniform buffers too:
bool Buffer::copy_from_cpu(const void* data, VkDeviceSize size)
{
  assert((m_usage == EUsage::STAGING) || (m_usage == EUsage::UNIFORM));

  return vmaCopyMemoryToAllocation(m_allocator, data, m_allocation, 0, size) == VK_SUCCESS;
}
Testing our uniform buffer
Before we get into matrices, let’s make sure the whole chain works with something simple: a colour, which the vertex shader multiplies with our vertex colours. Here’s the uniform block in default.vert:
#version 450

layout(location = 0) in vec3 in_pos;
layout(location = 1) in vec3 in_color;
layout(location = 2) in vec2 in_texcord;

layout(std140, set = 0, binding = 0) uniform VertexUniformData {
    vec3 overlay_colour;
} uniform_data;

layout(location = 0) out vec3 out_color;
layout(location = 1) out vec2 out_texcoord;

void main() {
    gl_Position = vec4(in_pos, 1.0);
    out_color = in_color * uniform_data.overlay_colour;
    out_texcoord = in_texcord;
}
The block lives in set 0, binding 0, and we access its members through the uniform_data name. Our texture moves over to set 1 in default.frag, and we bring back the vertex colours, multiplying them with the texture:
#version 450

layout(location = 0) in vec3 in_color;
layout(location = 1) in vec2 in_texcoord;

layout(set = 1, binding = 0) uniform sampler2D texture_sampler;

layout(location = 0) out vec4 finalColor;

void main() {
    finalColor = texture(texture_sampler, in_texcoord) * vec4(in_color, 1.0);
}
Why a separate set? Remember from the descriptors theory that sets let us group our resources by how often they change. Our uniform data is about to change every frame, while our texture never changes at all, so they go in different sets.
On the C++ side, here’s the matching struct, at the top of sample.cpp:
struct VertexUniformData
{
  glm::vec3 overlay_colour;
} g_vertex_uniform_data;
NOTE: Watch out for vec3s in std140 blocks! In std140, a vec3 is aligned to 16 bytes, like a vec4. A lone vec3 like ours is fine, but if we put two glm::vec3s one after the other in C++, the second one would sit at offset 12, while the shader expects it at offset 16. Our matrices won’t have this problem, as they’re made of 16 byte columns.
Our ShaderDataTable gets a new entry for the uniform buffer, and the texture moves to set 1:
    ShaderDataTable::create(
      m_device,
      std::initializer_list<ShaderDataTable::EntryDescription>{
        {.name = "vertex_uniform_data", .set = 0, .binding = 0, .type = VK_DESCRIPTOR_TYPE_UNIFORM_BUFFER, .count = 1, .stages = VK_SHADER_STAGE_VERTEX_BIT,},
        {.name = "texture_sampler", .set = 1, .binding = 0, .type = VK_DESCRIPTOR_TYPE_COMBINED_IMAGE_SAMPLER, .count = 1, .stages = VK_SHADER_STAGE_FRAGMENT_BIT,},
      }
    ),
The type is VK_DESCRIPTOR_TYPE_UNIFORM_BUFFER this time, and only the vertex stage needs to see it. This is where building ShaderDataTable the way we did pays off: it already creates a set layout per set, and the pool sizes and pipeline layout follow from the entries, so there’s nothing else to change there.
Next, a new member in sample.hpp, next to our other buffers:
Box<Buffer> m_vertex_uniform_buffer{};Which we reset in the destructor, along with the others:
m_vertex_uniform_buffer.reset();In initialize, right after creating our index buffer, we create the uniform buffer and fill it in:
  CHECK_RESULT(
    Buffer::create(
      m_allocator,
      sizeof(VertexUniformData),
      Buffer::EUsage::UNIFORM
    ),
    m_vertex_uniform_buffer
  );

  {
    g_vertex_uniform_data.overlay_colour = glm::vec3(1.0f, 0.0f, 0.0f);

    if (!m_vertex_uniform_buffer->copy_from_cpu(&g_vertex_uniform_data, sizeof(g_vertex_uniform_data))) {
      printf("Failed to copy data to uniform buffer\n");
      return false;
    }
  }
No staging buffer, no command buffer, no barriers. Just a copy straight from the CPU, thanks to the memory we picked.
Finally, we write the buffer into our descriptor set, right before the texture. This is the write_buffer_entry we wrote last time, finally getting some use:
  if (!m_shader_data_table->write_buffer_entry("vertex_uniform_data", m_vertex_uniform_buffer.get())) {
    printf("Failed to write uniform buffer to shader data table\n");
    return false;
  }
  if (!m_shader_data_table->write_image_entry("texture_sampler", m_texture_image.get(), m_texture_sampler)) {
We don’t pass an offset or a size, so the descriptor covers the whole buffer.
Run it, and our texture should only show its red channel now, strongest on the left and fading to black towards the right. That’s our red overlay multiplied with the vertex colours: the two left corners are red and magenta, which both have full red, and the two right corners are green and blue, which have none. Our uniform buffer works! Try changing the overlay to glm::vec3(1.0f) to get the full vertex colours back.
THEORY: Transformations
Now for the main event. Up until now, our vertex positions went straight into gl_Position, which meant we’ve been typing them directly in Vulkan’s normalized device coordinates (NDC): -1 to 1 on X and Y, no matter the window’s size or shape. That’s why our quad got stretched whenever the window wasn’t square.
To place things in a 3D world and look at them through a camera, we take each vertex through a series of spaces, using a matrix to get from one to the next:
- Model space (or local space): the coordinates we put in our vertex buffer, relative to the object’s own origin. Our quad’s corners are at
±0.5. - World space: where the object is in the world. The model matrix gets us here, by moving (translating), rotating and scaling the object.
- View space: the world, as seen from the camera. The camera sits at the origin, looking down the -Z axis, with +Y up (GLM follows OpenGL’s conventions here). The view matrix gets us here.
- Clip space: what
gl_Positionactually expects. The projection matrix gets us here, and it’s where perspective comes in.
After the vertex shader, the GPU divides gl_Position.xyz by gl_Position.w to get NDC. This is the perspective divide, and it’s what makes far away things smaller: a perspective projection matrix puts the distance from the camera into w, so the further away a vertex is, the more it gets divided. We’ve been setting w to 1.0 all along, which is why our positions went through untouched.
Why 4x4 matrices for 3D positions? A 3x3 matrix can rotate and scale, but it can’t translate. Adding a fourth component, w = 1.0 for positions, lets a 4x4 matrix do all three, and the projection too. And since they’re all 4x4 matrices, we can multiply them together into a single one. Order matters though: matrices apply right to left, so in
gl_Position = projection * view * model * vec4(in_pos, 1.0);the model matrix gets applied first, then the view, then the projection. Same goes for building a model matrix out of pieces, as we’ll see when we rotate our quad.
One last thing: GLM and GLSL both store matrices column-major (one column after another), and that’s exactly how std140 lays out a mat4: four vec4 columns, 64 bytes in total. So we can copy a glm::mat4 into our uniform buffer as is.
Model: moving our quad
Let’s swap our colour overlay for three matrices. In default.vert:
layout(std140, set = 0, binding = 0) uniform VertexUniformData {
    mat4 model;
    mat4 view;
    mat4 projection;
} uniform_data;

layout(location = 0) out vec3 out_color;
layout(location = 1) out vec2 out_texcoord;

void main() {
    gl_Position = uniform_data.projection * uniform_data.view * uniform_data.model * vec4(in_pos, 1.0);
    out_color = in_color;
    out_texcoord = in_texcord;
}
The vertex colours go back to being passed through as is, and the fragment shader goes back to only sampling the texture:
void main() {
    finalColor = texture(texture_sampler, in_texcoord);
}
The matching struct in sample.cpp:
struct VertexUniformData
{
  glm::mat4 model;
  glm::mat4 view;
  glm::mat4 projection;
} g_vertex_uniform_data;
GLM’s functions for building transformation matrices live in a separate header, so add it to common.hpp, right after glm.hpp:
#include <glm/glm.hpp>
#include <glm/gtc/matrix_transform.hpp>
And in initialize, instead of the overlay colour:
    g_vertex_uniform_data.model = glm::translate(glm::mat4(1.0f), glm::vec3(0.5f, 0.0f, 0.0f));
    g_vertex_uniform_data.view = glm::mat4(1.0f);
    g_vertex_uniform_data.projection = glm::mat4(1.0f);
glm::mat4(1.0f) is the identity matrix, which leaves everything as it is. glm::translate takes a matrix and returns it with a translation added on, here by 0.5 on X. With identity view and projection matrices, our quad should just move to the right:
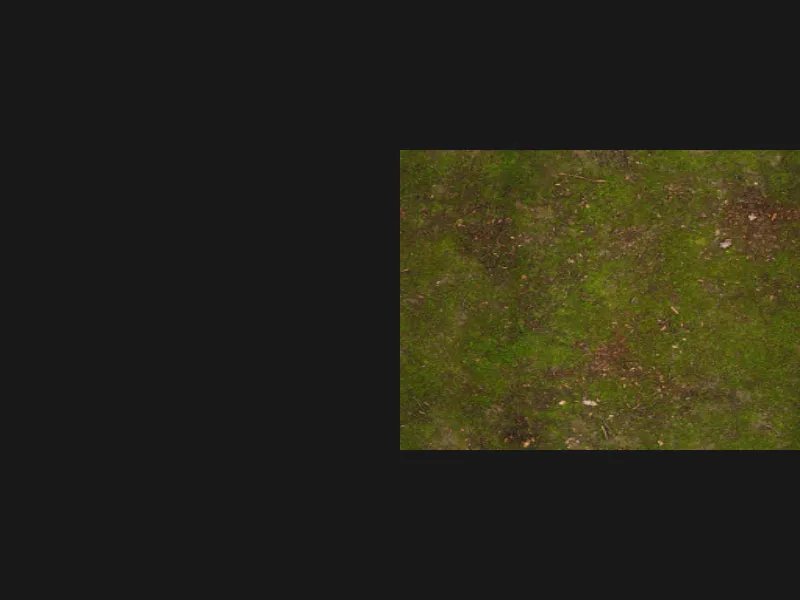
Half a unit to the right, which is a quarter of the window, since NDC spans 2 units across. And it’s still stretched, as we haven’t done anything about that yet.
Projection: adding perspective
Time for a real projection matrix:
    g_vertex_uniform_data.model = glm::translate(glm::mat4(1.0f), glm::vec3(0.0f, 0.0f, -0.75f));
    g_vertex_uniform_data.view = glm::mat4(1.0f);
    g_vertex_uniform_data.projection = glm::perspective(glm::half_pi<float>(), (float)m_swapchain_extent.width/(float)m_swapchain_extent.height, 0.1f, 1.0f);
glm::perspective takes:
- The vertical field of view, in radians.
glm::half_pi<float>()is 90°. - The aspect ratio: our swapchain’s width divided by its height. This is the part that undoes the stretching.
- The near and far planes:
0.1and1.0. Anything closer to the camera than the near plane, or further than the far plane, gets clipped away.
There’s a catch with those planes though. By default, GLM follows OpenGL, where depth in NDC goes from -1 at the near plane to 1 at the far plane. Vulkan’s goes from 0 to 1, and anything below 0 gets clipped. So with GLM’s default matrices, everything in the closer part of our range would be clipped away (with our near and far planes, the real near plane would end up at about 0.18 instead of 0.1), and half of our depth precision would be wasted. Luckily, GLM can produce Vulkan style matrices instead, if we define GLM_FORCE_DEPTH_ZERO_TO_ONE before including it. In common.hpp:
#define GLM_FORCE_DEPTH_ZERO_TO_ONE
#include <glm/glm.hpp>
#include <glm/gtc/matrix_transform.hpp>
It has to come before every GLM include, which is one more reason to keep them all in one place, in common.hpp. Nothing we’re drawing in this post is close enough to the camera to show the difference, but it’ll save us from some very confusing clipping once things get closer.
Notice that we also moved our quad 0.75 units down -Z. Our camera (our view space, for now) sits at the origin, looking down -Z, so our quad has to be in front of it to be seen. Left at z = 0, it’d be right on top of the camera, closer than our near plane, and clipped away entirely.
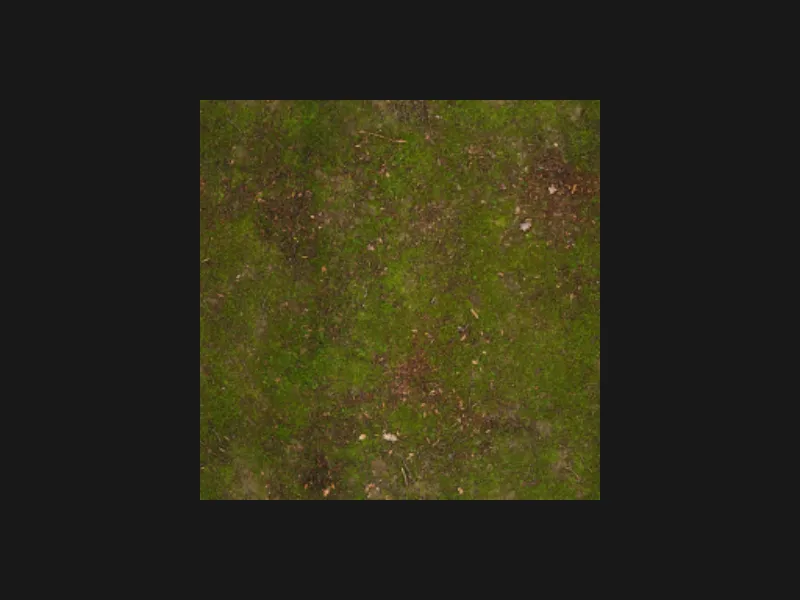
A proper square, at last! It’s also bigger than before: with a 90° field of view, at a distance of 0.75, we can see 0.75 units up and down from the centre, so our quad’s 0.5 covers two thirds of that.
View: placing the camera
Instead of moving our quad away from the camera, we could also move the camera away from the quad. That’s what the view matrix is for:
    g_vertex_uniform_data.model = glm::translate(glm::mat4(1.0f), glm::vec3(0.0f, 0.0f, 0.0f));
    g_vertex_uniform_data.view = glm::lookAt(glm::vec3(0.0f, 0.0f, 0.75f), glm::vec3(0.0f, 0.0f, 0.0f), glm::vec3(0.0f, 1.0f, 0.0f));
Our quad goes back to the origin, and glm::lookAt builds a camera from three vectors:
- Eye: where the camera is,
0.75units along +Z - Center: the point it’s looking at, the origin, where our quad is
- Up: which way is up for the camera, +Y
Exactly the same picture as before, and that’s the point! As far as the GPU is concerned, moving the camera back by 0.75 and moving the world forward by 0.75 are the same thing. In fact, that’s all a view matrix is: the inverse of the camera’s own transformation, moving the whole world so that the camera ends up at the origin, looking down -Z. Having it as a separate matrix just lets us think in terms of a camera, and keeps it apart from our objects’ own model matrices.
Correcting the projection
There’s one thing GLM and Vulkan don’t agree on. GLM was made for OpenGL, where +Y points up in clip space. In Vulkan, +Y points down. So far, everything we’ve rendered has been upside down, from the point of view of our 3D world: +Y on our quad goes down the screen.
The usual fix is to flip the Y axis in our projection matrix:
g_vertex_uniform_data.projection[1][1] *= -1.0f;[1][1] is column 1, row 1: the value that scales Y. Negating it flips our clip space Y, so +Y in our world now points up the screen, as it should.
Notice that the texture is now upside down compared to before! That’s because we set our texture coordinates up back when +Y pointed down: the corner at y = -0.5 got v = 0, the top row of the image, because it used to be at the top of the screen. Now it’s at the bottom. It doesn’t really matter for our ground texture, but if you’re using an image with text on it, flipping the v coordinates of the vertices will set it right.
NOTE: Another popular way of doing this is to flip the viewport instead, by giving it a negative height, which is allowed since Vulkan 1.1. Both work, but flipping the projection matrix keeps the fix in one place, right where the mismatch comes from.
Rotating our quad
Time to get things moving! We want the rotation to depend on time, so add #include <chrono> to the top of sample.cpp. Then, at the very top of draw_frame:
  {
    static constexpr float SPEED = glm::radians(90.0f);
    static auto prev_time = std::chrono::steady_clock::now();

    const auto current_time = std::chrono::steady_clock::now();
    const auto seconds = std::chrono::duration<float>(current_time - prev_time).count();

    g_vertex_uniform_data.model = glm::rotate(glm::mat4(1.0f), std::fmod(seconds * SPEED, glm::two_pi<float>()), glm::vec3(0.0f, 0.0f, 1.0f));
    m_vertex_uniform_buffer->copy_from_cpu(&g_vertex_uniform_data, sizeof(g_vertex_uniform_data));
}SPEED: How fast we rotate, in radians per second. 90° per second means a full turn every 4 seconds.- The time:
prev_timeis astatic, so it’s set once, on the first frame. Each frame, we take how many seconds have passed since then, as afloat. Using real time, rather than adding a fixed step every frame, keeps the rotation speed the same no matter how fast our frames are. - The angle:
seconds * SPEED, wrapped into0to2πwithstd::fmod. Without wrapping, the angle would keep growing, and afloatgets less and less precise the bigger it gets, which would eventually make our rotation jittery. glm::rotate: Takes a matrix, an angle and an axis to rotate around. The Z axis points straight at the camera, so our quad spins in place, like a wheel.
And since our model matrix now changes every frame, we copy our uniform data into the buffer every frame too.
NOTE: There’s a catch here, which we’re going to ignore for now. We have up to 3 frames in flight, but only one uniform buffer. When we write to it on the CPU for a new frame, the GPU may still be reading it for one of the previous frames! That’s a data race, and one that the validation layers can’t catch, since they don’t track our writes from the CPU. In practice, the worst we’d see here is a frame drawn with a slightly newer rotation, but it’s still wrong, and fixing it properly means one uniform buffer (and one descriptor set) per frame in flight. That’s enough new machinery for a post of its own, so to keep this one focused, we’ll tackle it in the next couple of posts.
Why we need a depth buffer
Before we build the whole cube, let’s try with just two of its faces: the back and the front. Our vertices now have a Z coordinate, half a unit behind and in front of the origin:
static const Vertex VERTICES[8] = {
  {glm::vec3(-0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f, -0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f,  0.5f, -0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3(-0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f, 0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f,  0.5f, 0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
};

static const uint32_t INDICES[12] = {
  0, 1, 2,
  2, 3, 0,

  4, 5, 6,
  6, 7, 4,
};
Our staging buffer is created with std::max(sizeof(VERTICES), sizeof(INDICES)), so it grows along with our data, no changes needed there.
We’ll rotate around the Y axis this time, so we can see the two faces swap places, and scale things down to a quarter so they fit nicely between our near and far planes:
    g_vertex_uniform_data.model =
      glm::rotate(glm::mat4(1.0f), std::fmod(seconds * SPEED, glm::two_pi<float>()), glm::vec3(0.0f, 1.0f, 0.0f))
      * glm::scale(glm::mat4(1.0f), glm::vec3(0.25f));
Remember, matrices apply right to left: we scale first, then rotate. The other way around wouldn’t make a difference here, as we’re scaling the same amount on every axis, but it would for anything else. Scaling an already rotated object along X would stretch it along whatever direction X happens to be in the world, rather than along its own X axis.
Run it, and for half of each turn, everything looks right:
But for the other half, the face at the back gets drawn over the face at the front:
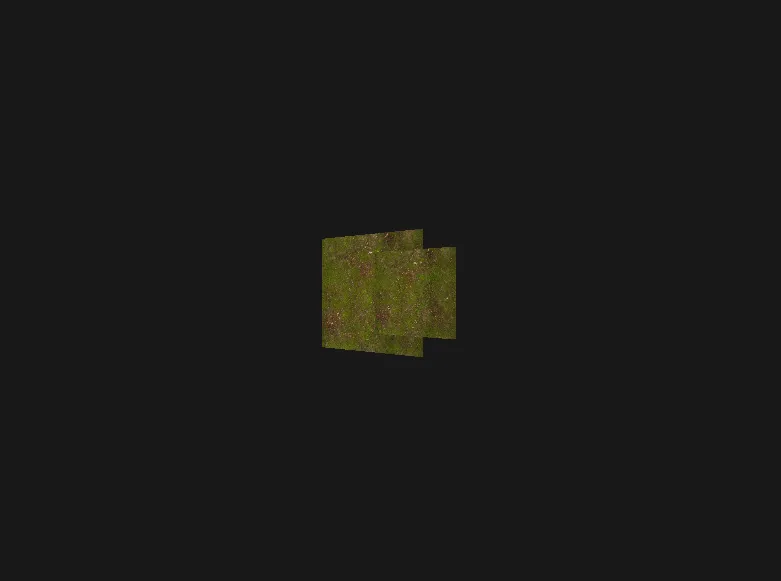
The GPU draws our triangles in the order we give them, and anything drawn later simply overwrites what’s already there. Our z = 0.5 face comes second in our index buffer, so it always ends up on top: correct while it’s the one facing the camera, and wrong once it has rotated around to the back.
We could sort our triangles from back to front every frame, and draw them in that order (the painter’s algorithm), but that gets expensive fast, and it can’t handle triangles that cut through each other. Instead, we let the GPU sort it out, one pixel at a time.
THEORY: Depth buffering
A depth buffer is an image the same size as our colour attachment, holding a depth value for every pixel: how far away the closest thing drawn to that pixel so far is. In Vulkan, depth values go from 0.0, the closest, to 1.0, the furthest. Each frame, it works like this:
- Clear the depth buffer to
1.0, the furthest possible depth - For every fragment we draw, the GPU compares its depth against the value already in the depth buffer (the depth test). With the compare op
LESS, the fragment passes only if it’s closer than what’s already there - If it passes, the fragment’s colour gets written, and so does its depth (the depth write), so that anything drawn later has to be closer still. If it fails, the fragment is thrown away
The order we draw things in no longer matters: whatever’s closest to the camera wins, pixel by pixel. And the GPU can often run the test before the fragment shader (early fragment tests), saving the work for fragments that would be hidden anyway.
In Vulkan, a depth buffer is just an image, with a depth format, used as a depth attachment while rendering. We already have an Image class, so most of the work is done!
Creating the depth attachment
An image view needs to know which aspect of the image it’s looking at: colour or depth. Our Image::create always asked for the colour aspect, so let’s add a small helper to Image, in image.hpp:
static bool is_depth_format(VkFormat format);And in image.cpp:
bool Image::is_depth_format(VkFormat format)
{
  switch(format)
  {
    case VK_FORMAT_D16_UNORM:
    case VK_FORMAT_D32_SFLOAT:
    case VK_FORMAT_D16_UNORM_S8_UINT:
    case VK_FORMAT_D24_UNORM_S8_UINT:
    case VK_FORMAT_D32_SFLOAT_S8_UINT:
      return true;

    default:
      return false;
  }
}
These are all of Vulkan’s formats with a depth component. Some of them have a stencil component too (the S8), which we won’t need. Then, in Image::create, the view’s aspect depends on the format:
.aspectMask = is_depth_format(format) ? VK_IMAGE_ASPECT_DEPTH_BIT : VK_IMAGE_ASPECT_COLOR_BIT,Our depth attachment has to be the same size as the swapchain images we render into, so it gets created along with them, and recreated whenever they are. In sample.hpp, next to our swapchain members:
Box<Image> m_depth_attachment{};In recreate_swapchain, we destroy the old one along with the old swapchain image views:
  m_depth_attachment.reset();
  for (const auto &view : m_swapchain_image_views)
    vkDestroyImageView(m_device, view, nullptr);
And create the new one at the end, after creating the new swapchain image views:
  CHECK_RESULT(
    Image::create(
      m_device,
      m_allocator,
      VK_FORMAT_D32_SFLOAT,
      m_swapchain_extent,
      VK_IMAGE_USAGE_DEPTH_STENCIL_ATTACHMENT_BIT
    ),
    m_depth_attachment
  );
  if (!execute_single_shot_commands([&](VkCommandBuffer cmd) -> Result<>
    {
      if (!m_depth_attachment->transition_layout(cmd, VK_IMAGE_LAYOUT_DEPTH_ATTACHMENT_OPTIMAL))
        return "Failed to transition depth image layout";

      return Ok();
    })
  )
return false;- The format:
VK_FORMAT_D32_SFLOAT, a 32-bit float per pixel, and nothing else. It’s very widely supported as a depth attachment, and gives us plenty of precision. - The usage:
VK_IMAGE_USAGE_DEPTH_STENCIL_ATTACHMENT_BIT, as we’ll only ever use it as a depth attachment. - The layout transition: Remember the
UNDEFINED→DEPTH_ATTACHMENT_OPTIMALcase we added to our layout transitions back in the coloured window post? This is where it finally gets used! Our depth attachment never gets used for anything else, so it can stay in this layout for its whole life, and we only need to transition it once, right after creating it.
And in the destructor, before the VMA allocator gets destroyed:
m_depth_attachment.reset();There’s one problem though. recreate_swapchain also gets called while creating our device, from create_device_and_swapchain, and creating our depth attachment needs the VMA allocator and the single shot command resources. Until now, we created both in initialize, after create_device_and_swapchain. So let’s move them up: cut them out of initialize, and paste them into create_device_and_swapchain, right after we get our queues:
  vkGetDeviceQueue(m_device, m_graphics_queue_family_index, 0, &m_graphics_queue);
  vkGetDeviceQueue(m_device, m_present_queue_family_index, 0, &m_present_queue);

  VmaAllocatorCreateInfo vma_create_info{
    .physicalDevice = m_physical_device,
    .device = m_device,
    .instance = m_instance,
    .vulkanApiVersion = VK_API_VERSION_1_3,
  };
  if (vmaCreateAllocator(&vma_create_info, &m_allocator) != VK_SUCCESS) {
    printf("Failed to create the VMA allocator\n");
    return false;
  }

  {
    VkCommandPoolCreateInfo pool_create_info{
      .sType = VK_STRUCTURE_TYPE_COMMAND_POOL_CREATE_INFO,
      .flags = VK_COMMAND_POOL_CREATE_RESET_COMMAND_BUFFER_BIT,
      .queueFamilyIndex = m_graphics_queue_family_index,
    };
    if (vkCreateCommandPool(m_device, &pool_create_info, nullptr, &m_single_shot_command_pool) != VK_SUCCESS) {
      printf("Failed to create the single shot command pool\n");
      return false;
    }

    VkFenceCreateInfo fence_create_info{
      .sType = VK_STRUCTURE_TYPE_FENCE_CREATE_INFO,
    };
    if (vkCreateFence(m_device, &fence_create_info, nullptr, &m_single_shot_command_fence) != VK_SUCCESS) {
      printf("Failed to create the single shot fence\n");
      return false;
    }

    VkCommandBufferAllocateInfo alloc_info{
      .sType = VK_STRUCTURE_TYPE_COMMAND_BUFFER_ALLOCATE_INFO,
      .commandPool = m_single_shot_command_pool,
      .level = VK_COMMAND_BUFFER_LEVEL_PRIMARY,
      .commandBufferCount = 1,
    };
    if (vkAllocateCommandBuffers(m_device, &alloc_info, &m_single_shot_command_buffer) != VK_SUCCESS) {
      printf("Failed to allocate the single shot command buffer\n");
      return false;
    }
  }
The code itself is unchanged, only its location. initialize now goes straight from create_device_and_swapchain to create_frame_resources:
  if (!create_device_and_swapchain())
    return false;

  if (!create_frame_resources())
    return false;
Using the depth attachment
Our pipeline needs to know about the depth attachment too. Pipeline::create gets a new parameter for its format, in both pipeline.hpp and pipeline.cpp:
Result<Box<Pipeline>> Pipeline::create(VkDevice device,
        VkFormat color_attachment_format,
        VkFormat depth_attachment_format,
Which goes into our VkPipelineRenderingCreateInfo, where we’ve been leaving it UNDEFINED until now:
.depthAttachmentFormat = depth_attachment_format,Then we turn the depth test on, with a new VkPipelineDepthStencilStateCreateInfo, right before our VkGraphicsPipelineCreateInfo:
  VkPipelineDepthStencilStateCreateInfo depth_stencil_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_DEPTH_STENCIL_STATE_CREATE_INFO,
    .depthTestEnable = true,
    .depthWriteEnable = true,
    .depthCompareOp = VK_COMPARE_OP_LESS,
    .minDepthBounds = 0.0f,
    .maxDepthBounds = 1.0f,
};depthTestEnableanddepthWriteEnable: The depth test and the depth write, from our theory section. We want both.depthCompareOp:VK_COMPARE_OP_LESS, so a fragment passes only if it’s closer than what’s already there.minDepthBoundsandmaxDepthBounds: These are for the optional depth bounds test, which we’re not enabling, so they don’t matter.0.0to1.0covers the whole depth range anyway.
The stencil test stays off, as everything we leave out is zero initialized. And we hand it to the pipeline:
.pDepthStencilState = &depth_stencil_state_create_info,In initialize, we pass our depth attachment’s format, right after the swapchain’s:
    Pipeline::create(
      m_device,
      m_swapchain_format.format,
      m_depth_attachment->get_format(),
This works because our depth attachment already exists by the time we get here, created by recreate_swapchain. Another reason it was worth moving those things around!
Last but not least, draw_frame. Right after our color_attachment_info, we describe the depth attachment:
  VkRenderingAttachmentInfo depth_attachment_info{
      .sType = VK_STRUCTURE_TYPE_RENDERING_ATTACHMENT_INFO,
      .imageView = m_depth_attachment->get_view(),
      .imageLayout = VK_IMAGE_LAYOUT_DEPTH_ATTACHMENT_OPTIMAL,
      .loadOp = VK_ATTACHMENT_LOAD_OP_CLEAR,
      .storeOp = VK_ATTACHMENT_STORE_OP_DONT_CARE,
      .clearValue =
          {
              .depthStencil =
                  {
                      1.0f,
                      0,
                  },
          },
};loadOp:CLEAR, to start every frame from scratchclearValue: A depth of1.0, the furthest possible, so that anything we draw is closer. The0is the stencil value, which we don’t usestoreOp:DONT_CARE. Unlike our colour attachment, nobody needs the depth values once the frame is done, and telling the GPU it can throw them away can save it some work
And add it to our VkRenderingInfo:
      .colorAttachmentCount = 1,
      .pColorAttachments = &color_attachment_info,
      .pDepthAttachment = &depth_attachment_info,
Run it again:
The face in front is always in front now, no matter the order we draw them in!
Making it a cube
Two faces down, four to go! You might think 8 vertices would be enough for a cube, one for each corner. But every corner is shared by three faces, and each face needs its own texture coordinates at that corner, to show the whole texture. A vertex is the whole package (position, colour and texture coordinates), so we need 4 vertices per face, 24 in total:
static const Vertex VERTICES[24] = {
  {glm::vec3(-0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f, -0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f,  0.5f, -0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3(-0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f, 0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f,  0.5f, 0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3( -0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( -0.5f,  0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3(-0.5f,  0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f, -0.5f, 0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3(0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3(0.5f,  0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3(0.5f,  0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(0.5f, -0.5f, 0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3(-0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f, -0.5f,  0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f, -0.5f,  0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},

  {glm::vec3(-0.5f,  0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
  {glm::vec3( 0.5f,  0.5f,  0.5f), glm::vec3(0.0f, 0.0f, 1.0f)  , glm::vec2(1.0f, 1.0f)},
  {glm::vec3(-0.5f,  0.5f,  0.5f),  glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
};
In order: the back and front faces we already had, then the left (x = -0.5), right (x = 0.5), bottom (y = -0.5) and top (y = 0.5) faces. Each face is still two triangles, so the indices follow the same pattern as before, 6 per face:
static const uint32_t INDICES[36] = {
  0, 1, 2,
  2, 3, 0,

  4, 5, 6,
  6, 7, 4,

  8, 9, 10,
  10, 11, 8,

  12, 13, 14,
  14, 15, 12,

  16, 17, 18,
  18, 19, 16,

  20, 21, 22,
  22, 23, 20,
};
Our vkCmdDrawIndexed call already uses sizeof(INDICES)/sizeof(INDICES[0]) for the index count, so it picks up all 36 indices on its own.
To show off all the faces, we’ll rotate around a diagonal axis, (1, 1, 1), instead of the Y axis:
    g_vertex_uniform_data.model =
      glm::rotate(glm::mat4(1.0f), std::fmod(seconds * SPEED, glm::two_pi<float>()), glm::vec3(1.0f, 1.0f, 1.0f))
      * glm::scale(glm::mat4(1.0f), glm::vec3(0.25f));
The axis isn’t of unit length, but that’s fine: glm::rotate normalizes it for us.
A spinning cube!
NOTE: You might be wondering about the faces we can’t see. Right now, the GPU rasterizes all 12 triangles every frame, including the ones facing away from the camera, and the depth test then throws their fragments away. A common optimization is back-face culling: telling the pipeline to skip triangles facing away from the camera entirely, based on their winding order (whether their vertices go clockwise or counter-clockwise on screen). Our pipeline has culling turned off (VK_CULL_MODE_NONE), and that’s a good thing for now, as our cube’s faces don’t wind consistently: the back and front faces use the same index pattern, which makes them wind in opposite directions as seen from outside the cube. Turning culling on as is would hide half of our faces! On top of that, the Y flip in our projection also flips the winding on screen. We’ll sort all of that out in the next couple of posts.
Handling window resizes
There’s one problem left. Try resizing the window, and our cube gets stretched again! That’s because we only build our projection matrix once, in initialize, using the swapchain’s size at the time. When the window gets resized, our swapchain gets recreated with the new size, but our aspect ratio stays the same.
We already have a function that gets called whenever the swapchain’s size changes: recreate_swapchain. So let’s build our projection matrix there instead, right at the end:
  g_vertex_uniform_data.projection = glm::perspective(glm::half_pi<float>(), (float)m_swapchain_extent.width/(float)m_swapchain_extent.height, 0.1f, 1.0f);
  g_vertex_uniform_data.projection[1][1] *= -1.0f;

  m_swapchain_is_out_of_date = false;
And remove it from initialize, which now only sets the model and view matrices:
  {
    g_vertex_uniform_data.model = glm::translate(glm::mat4(1.0f), glm::vec3(0.0f, 0.0f, 0.0f));
    g_vertex_uniform_data.view = glm::lookAt(glm::vec3(0.0f, 0.0f, 0.75f), glm::vec3(0.0f, 0.0f, 0.0f), glm::vec3(0.0f, 1.0f, 0.0f));

    if (!m_vertex_uniform_buffer->copy_from_cpu(&g_vertex_uniform_data, sizeof(g_vertex_uniform_data))) {
recreate_swapchain also runs once at startup, from create_device_and_swapchain, so our projection matrix is ready before the first frame. And since draw_frame copies the whole of g_vertex_uniform_data into the uniform buffer every frame, the new projection reaches our shader on the very next frame after a resize.
While we’re at it, prev_time was never a great name for something that’s only set once, on the first frame, so I’ve renamed it to start_time:
    static auto start_time = std::chrono::steady_clock::now();

    const auto current_time = std::chrono::steady_clock::now();
    const auto seconds = std::chrono::duration<float>(current_time - start_time).count();
Resize away, and our cube stays a cube!
Wrapping up
And that’s it! Build it, run it, and you should see a textured cube spinning in front of you, with no validation errors.
Let’s recap what we did:
- Added uniform buffers to our
Bufferclass, in memory we can write to directly from the CPU - Tested one out with a colour overlay, using a second descriptor set and
write_buffer_entry - Learned about model, view and projection matrices, the spaces they take us through, and the perspective divide
- Moved our quad with
glm::translate, and gave it perspective withglm::perspective, fixing our stretched aspect ratio, and made GLM use Vulkan’s0to1depth range - Placed a camera with
glm::lookAt - Flipped Y in our projection matrix, to make up for the difference between GLM’s and Vulkan’s clip spaces
- Set our quad rotating with
glm::rotate, updating our uniform buffer every frame - Saw what goes wrong without a depth buffer, then created a depth attachment and turned on the depth test
- Turned our quad into a cube, with 24 vertices and 36 indices
- Rebuilt our projection matrix on every swapchain recreation, to keep our aspect ratio right after a resize
Go ahead and play around with it! Change the camera’s position in glm::lookAt, try a narrower or wider field of view, rotate around different axes, or give the cube a translation and watch it orbit (hint: try rotating after translating). And try setting depthTestEnable to false to see our artifact come back.
Next up: Structuring the Codebase
Our codebase has grown quite a bit, so next we’ll take some time to restructure it and keep it maintainable. Then, we’ll fix our uniform buffer data race, with buffers and descriptor sets for each frame in flight.
In the post after that, we’ll sort out our cube’s winding order and turn on back-face culling. And we’ll restructure our render loop around how often our data changes: the projection matrix goes into a rarely updated descriptor set, the view matrix into a set updated every frame, and the model matrix into a push constant, which we first mentioned all the way back in the coloured triangle post.
References
- GLM, and its manual
- LearnOpenGL: Coordinate Systems
- LearnOpenGL: Depth testing
- Vulkan Memory Allocator: Recommended usage patterns
- Sascha Willems: Flipping the Vulkan viewport
- VkGuide
- The Vulkan specification (version 1.4.364 at the time of writing)
Full Source Code
The complete sample is now just over 2300 lines in total, across the same files as last time. That’s not counting stb_image.hpp, which is the unmodified stb_image.h from stb. The resources/ folder, with the texture and the compiled shaders, can be found in the GitHub repo along with everything else.
Show CMakeLists.txt
cmake_minimum_required(VERSION 3.28)

set(CMAKE_CXX_STANDARD 20)
set(CMAKE_CXX_STANDARD_REQUIRED ON)
set(CMAKE_CXX_EXTENSIONS OFF)
set(CMAKE_EXPORT_COMPILE_COMMANDS ON)

project(I_A_S_ME_VulkanSeries)

include(FetchContent)

set(GLFW_BUILD_EXAMPLES OFF CACHE BOOL "" FORCE)
set(GLFW_BUILD_TESTS OFF CACHE BOOL "" FORCE)
set(GLFW_BUILD_DOCS OFF CACHE BOOL "" FORCE)

FetchContent_Declare(glfw
    GIT_REPOSITORY https://github.com/glfw/glfw.git
    GIT_TAG 3.5.1
    GIT_SHALLOW TRUE
)

FetchContent_Declare(VulkanMemoryAllocator
    GIT_REPOSITORY https://github.com/GPUOpen-LibrariesAndSDKs/VulkanMemoryAllocator.git
    GIT_TAG v3.5.0
    GIT_SHALLOW TRUE
)

FetchContent_Declare(glm
    GIT_REPOSITORY https://github.com/g-truc/glm.git
    GIT_TAG 1.0.3
    GIT_SHALLOW TRUE
)

FetchContent_MakeAvailable(glfw VulkanMemoryAllocator glm)

add_executable(App
    vma.cpp
    main.cpp
    image.cpp
    buffer.cpp
    sample.cpp
    pipeline.cpp
    shader_data_table.cpp
)

target_link_libraries(App PRIVATE
    glfw
    vulkan
    glm::glm
    GPUOpen::VulkanMemoryAllocator
)
Show common.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#pragma once

#include <map>
#include <span>
#include <deque>
#include <cstdio>
#include <memory>
#include <string>
#include <cstddef>
#include <variant>
#include <cassert>
#include <type_traits>

#define GLFW_INCLUDE_VULKAN
#include <GLFW/glfw3.h>

#include <vk_mem_alloc.h>

#define GLM_FORCE_DEPTH_ZERO_TO_ONE
#include <glm/glm.hpp>
#include <glm/gtc/matrix_transform.hpp>

#define CHECK_RESULT(_result, _var)             \
{                                               \
  auto result = _result;                        \
  if (result.is_error()) {                      \
    printf("%s\n", result.get_error().c_str()); \
    return false;                               \
  }                                             \
  _var = std::move(result).take_value();        \
}

struct Ok {};

// A very simple Result type to hold either
// an error message or the value. To be used
// mostly as return types in failable functions.
template<typename T = Ok>
class [[nodiscard]] Result
{
    static_assert(!std::is_same_v<std::decay_t<T>, std::string>, "std::string values are not allowed");
    static_assert(!std::is_same_v<T, void>, "void values are not allowed. Use Result<> or Result<Ok> instead.");

public:
    Result(std::nullptr_t) = delete;

    constexpr Result(const char* error): m_variant(std::in_place_index<1>, error) {}
    constexpr Result(T&& value): m_variant(std::in_place_index<0>, std::move(value)) {}
    constexpr Result(const std::string& error): m_variant(std::in_place_index<1>, error) {}

    constexpr bool is_ok() const { return m_variant.index() == 0; }
    constexpr bool is_error() const { return m_variant.index() == 1; }

    T get_value() && = delete;
    T& get_value() & { assert(is_ok()); return std::get<0>(m_variant); }
    const T& get_value() const& { assert(is_ok()); return std::get<0>(m_variant); }

    T take_value() && { assert(is_ok()); return std::get<0>(std::move(m_variant)); }

    const std::string& get_error() const& { assert(is_error()); return std::get<1>(m_variant); }
    std::string get_error() && { assert(is_error()); return std::get<1>(std::move(m_variant)); }

private:
    std::variant<T, std::string> m_variant;
};

// Alias std::unique_ptr to Box. Easier to type.
// (Inspired by Rust of course, just like Result above).
template<typename T>
using Box = std::unique_ptr<T>;
Show buffer.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#pragma once

#include "common.hpp"

class Buffer
{
public:
    enum class EUsage
    {
        VERTEX,
        INDEX,
        UNIFORM,
        STAGING,
    };

public:
    static Result<Box<Buffer>> create(VmaAllocator allocator, VkDeviceSize size, EUsage usage);

    Buffer(const Buffer&) = delete;
    ~Buffer();

    void bind(VkCommandBuffer cmd);

    VkDeviceSize get_size() const { return m_size; }

    VkBuffer get_handle() const { return m_handle; }

    bool copy_from_cpu(const void* data, VkDeviceSize size);

private:
    Buffer(VmaAllocator allocator): m_allocator(allocator) {}

private:
    EUsage m_usage{};
    VmaAllocator m_allocator{};

    VkBuffer m_handle{};
    VkDeviceSize m_size{};
    VmaAllocation m_allocation{};
};```

</details>

<details>
<summary>Show buffer.cpp</summary>

```cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#include "buffer.hpp"

Result<Box<Buffer>> Buffer::create(VmaAllocator allocator, VkDeviceSize size, EUsage usage)
{
  Box<Buffer> buffer{new Buffer(allocator)};

  buffer->m_size = size;
  buffer->m_usage = usage;

  VkBufferUsageFlags _usage{};
  VmaAllocationCreateFlags _mem_flags{};

  switch (usage) {
    case EUsage::VERTEX:
      // vertex buffer + transfer dst (for copying data in from staging buffer)
      _usage = VK_BUFFER_USAGE_TRANSFER_DST_BIT | VK_BUFFER_USAGE_VERTEX_BUFFER_BIT;
      break;

    case EUsage::INDEX:
      // index buffer + transfer dst (for copying data in from staging buffer)
      _usage = VK_BUFFER_USAGE_TRANSFER_DST_BIT | VK_BUFFER_USAGE_INDEX_BUFFER_BIT;
      break;

    case EUsage::UNIFORM:
      // uniform buffer
      _usage = VK_BUFFER_USAGE_UNIFORM_BUFFER_BIT;

      // allow writing to this buffer from CPU memory
      _mem_flags = VMA_ALLOCATION_CREATE_HOST_ACCESS_SEQUENTIAL_WRITE_BIT;
      break;

    case EUsage::STAGING:
      // allows transferring data out from this buffer (for copying)
      _usage = VK_BUFFER_USAGE_TRANSFER_SRC_BIT;

      // allow writing to this buffer from CPU memory
      _mem_flags = VMA_ALLOCATION_CREATE_HOST_ACCESS_SEQUENTIAL_WRITE_BIT;
      break;
  }

  VkBufferCreateInfo create_info{
    .sType = VK_STRUCTURE_TYPE_BUFFER_CREATE_INFO,
    .size = size,
    .usage = _usage,
    .sharingMode = VK_SHARING_MODE_EXCLUSIVE, // we only need to use our buffers from a single queue family at a time
  };

  VmaAllocationCreateInfo alloc_create_info{
    .flags = _mem_flags,
    .usage = VMA_MEMORY_USAGE_AUTO, // when _mem_flags doesn't contain CPU access flags (like we set in above switch STAGING case), this picks fast GPU VRAM
  };

  if (vmaCreateBuffer(allocator, &create_info, &alloc_create_info, &buffer->m_handle, &buffer->m_allocation, nullptr) != VK_SUCCESS) {
    return "Failed to create the buffer";
  }

  return buffer;
}

Buffer::~Buffer()
{
  if (m_allocator && m_handle && m_allocation)
    vmaDestroyBuffer(m_allocator, m_handle, m_allocation);
}

void Buffer::bind(VkCommandBuffer cmd)
{
  switch (m_usage) {
    case EUsage::VERTEX:
    {
      VkDeviceSize offset = 0;
      vkCmdBindVertexBuffers(cmd, 0, 1, &m_handle, &offset);
    }
    break;

    case EUsage::INDEX:
      vkCmdBindIndexBuffer(cmd, m_handle, 0, VK_INDEX_TYPE_UINT32);
    break;

    // we shouldn't call bind on a staging or uniform buffer
    case EUsage::UNIFORM:
    case EUsage::STAGING:
      assert(false);
    break;
  }
}

bool Buffer::copy_from_cpu(const void* data, VkDeviceSize size)
{
  assert((m_usage == EUsage::STAGING) || (m_usage == EUsage::UNIFORM));

  return vmaCopyMemoryToAllocation(m_allocator, data, m_allocation, 0, size) == VK_SUCCESS;
}
Show image.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.
#pragma once
#include "buffer.hpp"
class Image
{
public:
static bool is_depth_format(VkFormat format);
static bool load_rgba_from_file(const std::string& path, std::vector<uint8_t>& pixels, VkExtent2D& extent);
static bool transition_image_layout(VkCommandBuffer cmd, VkImage image, VkImageLayout old_layout, VkImageLayout new_layout,
uint32_t base_mip_level = 0, uint32_t level_count = 1, uint32_t base_array_layer = 0,
uint32_t layer_count = 1);
public:
static Result<Box<Image>> create(VkDevice device, VmaAllocator allocator, VkFormat format, VkExtent2D extent, VkImageUsageFlags usage);
Image(const Image&) = delete;
~Image();
bool transition_layout(VkCommandBuffer cmd, VkImageLayout new_layout);
// make sure the image is in VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL layout before
// calling this function
bool copy_from_cpu(VkCommandBuffer cmd, const void* data, VkDeviceSize size);
VkImageView get_view() const { return m_view_handle; }
VkImageLayout get_layout() const { return m_layout; }
VkFormat get_format() const { return m_format; }
private:
Image(VkDevice device, VmaAllocator allocator): m_device(device), m_allocator(allocator) {}
private:
VkDevice m_device{};
VmaAllocator m_allocator{};
VkImage m_handle{};
VkImageView m_view_handle{};
VkFormat m_format{};
VkExtent2D m_extent{};
VmaAllocation m_allocation{};
VkImageLayout m_layout{VK_IMAGE_LAYOUT_UNDEFINED};
Box<Buffer> m_staging_buffer; // only create if copy_from_cpu is called
};```
</details>
<details>
<summary>Show image.cpp</summary>
```cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.
#include "image.hpp"
#define STB_IMAGE_IMPLEMENTATION
#include "stb_image.hpp"
Result<Box<Image>> Image::create(VkDevice device, VmaAllocator allocator, VkFormat format, VkExtent2D extent, VkImageUsageFlags usage)
{
Box<Image> image(new Image(device, allocator));
image->m_format = format;
image->m_extent = extent;
VkImageCreateInfo create_info{
.sType = VK_STRUCTURE_TYPE_IMAGE_CREATE_INFO,
.imageType = VK_IMAGE_TYPE_2D, // for now we'll only need 2D images
.format = format,
.extent = VkExtent3D(extent.width, extent.height, 1),
.mipLevels = 1, // we won't be bothering with mip mapping for now
.arrayLayers = 1,
.samples = VK_SAMPLE_COUNT_1_BIT, // we won't be bothering with multisampling for now either
.tiling = VK_IMAGE_TILING_OPTIMAL, // we don't have any specific tiling we need so let vulkan pick the optimal one
.usage = usage,
.sharingMode = VK_SHARING_MODE_EXCLUSIVE, // we only need to use our images from a single queue family at a time
.initialLayout = image->m_layout,
};
VmaAllocationCreateInfo alloc_create_info{
.usage = VMA_MEMORY_USAGE_AUTO,
};
if (vmaCreateImage(allocator, &create_info, &alloc_create_info, &image->m_handle, &image->m_allocation, nullptr) != VK_SUCCESS)
return "Failed to create the image";
VkImageViewCreateInfo view_create_info{
.sType = VK_STRUCTURE_TYPE_IMAGE_VIEW_CREATE_INFO,
.image = image->m_handle,
.viewType = VK_IMAGE_VIEW_TYPE_2D,
.format = image->m_format,
.subresourceRange = {
.aspectMask = is_depth_format(format) ? VK_IMAGE_ASPECT_DEPTH_BIT : VK_IMAGE_ASPECT_COLOR_BIT,
.baseMipLevel = 0,
.levelCount = 1,
.baseArrayLayer = 0,
.layerCount = 1,
},
};
if (vkCreateImageView(device, &view_create_info, nullptr, &image->m_view_handle) != VK_SUCCESS)
return "Failed to create the image view";
return image;
}
Image::~Image()
{
m_staging_buffer.reset();
if (m_device && m_view_handle)
vkDestroyImageView(m_device, m_view_handle, nullptr);
if (m_allocator && m_allocation && m_handle)
vmaDestroyImage(m_allocator, m_handle, m_allocation);
}
bool Image::transition_layout(VkCommandBuffer cmd, VkImageLayout new_layout)
{
if (transition_image_layout(cmd, m_handle, m_layout, new_layout)) {
m_layout = new_layout;
return true;
}
return false;
}
bool Image::copy_from_cpu(VkCommandBuffer cmd, const void* data, VkDeviceSize size)
{
assert(m_layout == VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL);
if (!m_staging_buffer || (m_staging_buffer->get_size() < size)) {
m_staging_buffer.reset();
CHECK_RESULT(
Buffer::create(
m_allocator,
size,
Buffer::EUsage::STAGING
),
m_staging_buffer
);
}
if (!m_staging_buffer->copy_from_cpu(data, size))
return false;
VkBufferImageCopy region{
.bufferOffset = 0,
.bufferRowLength = m_extent.width,
.bufferImageHeight = m_extent.height,
.imageSubresource = {
.aspectMask = VK_IMAGE_ASPECT_COLOR_BIT,
.mipLevel = 0,
.baseArrayLayer = 0,
.layerCount = 1,
},
.imageOffset = {},
.imageExtent = VkExtent3D(m_extent.width, m_extent.height, 1),
};
vkCmdCopyBufferToImage(cmd, m_staging_buffer->get_handle(), m_handle, VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL, 1, ®ion);
return true;
}
bool Image::transition_image_layout(VkCommandBuffer cmd, VkImage image, VkImageLayout old_layout,
VkImageLayout new_layout, uint32_t base_mip_level, uint32_t level_count,
uint32_t base_array_layer, uint32_t layer_count)
{
VkPipelineStageFlags2 src_stage{}, dst_stage{};
VkAccessFlags2 src_access{}, dst_access{};
VkImageAspectFlags aspect{VK_IMAGE_ASPECT_COLOR_BIT};
#define _is_layout_pair(o, n) ((old_layout == o) && (new_layout == n))
if (_is_layout_pair(VK_IMAGE_LAYOUT_UNDEFINED, VK_IMAGE_LAYOUT_COLOR_ATTACHMENT_OPTIMAL))
{
src_stage = VK_PIPELINE_STAGE_2_COLOR_ATTACHMENT_OUTPUT_BIT;
src_access = VK_ACCESS_2_NONE;
dst_stage = VK_PIPELINE_STAGE_2_COLOR_ATTACHMENT_OUTPUT_BIT;
dst_access = VK_ACCESS_2_COLOR_ATTACHMENT_WRITE_BIT;
}
else if (_is_layout_pair(VK_IMAGE_LAYOUT_UNDEFINED, VK_IMAGE_LAYOUT_DEPTH_ATTACHMENT_OPTIMAL))
{
src_stage = VK_PIPELINE_STAGE_2_EARLY_FRAGMENT_TESTS_BIT | VK_PIPELINE_STAGE_2_LATE_FRAGMENT_TESTS_BIT;
src_access = VK_ACCESS_2_DEPTH_STENCIL_ATTACHMENT_WRITE_BIT;
dst_stage = VK_PIPELINE_STAGE_2_EARLY_FRAGMENT_TESTS_BIT | VK_PIPELINE_STAGE_2_LATE_FRAGMENT_TESTS_BIT;
dst_access = VK_ACCESS_2_DEPTH_STENCIL_ATTACHMENT_READ_BIT | VK_ACCESS_2_DEPTH_STENCIL_ATTACHMENT_WRITE_BIT;
aspect = VK_IMAGE_ASPECT_DEPTH_BIT;
}
else if (_is_layout_pair(VK_IMAGE_LAYOUT_COLOR_ATTACHMENT_OPTIMAL, VK_IMAGE_LAYOUT_PRESENT_SRC_KHR))
{
src_stage = VK_PIPELINE_STAGE_2_COLOR_ATTACHMENT_OUTPUT_BIT;
src_access = VK_ACCESS_2_COLOR_ATTACHMENT_WRITE_BIT;
dst_stage = VK_PIPELINE_STAGE_2_NONE;
dst_access = VK_ACCESS_2_NONE;
}
else if (_is_layout_pair(VK_IMAGE_LAYOUT_UNDEFINED, VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL)) {
src_stage = VK_PIPELINE_STAGE_2_NONE;
src_access = VK_ACCESS_2_NONE;
dst_stage = VK_PIPELINE_STAGE_2_COPY_BIT;
dst_access = VK_ACCESS_2_TRANSFER_WRITE_BIT;
}
else if (_is_layout_pair(VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL, VK_IMAGE_LAYOUT_SHADER_READ_ONLY_OPTIMAL)) {
src_stage = VK_PIPELINE_STAGE_2_COPY_BIT;
src_access = VK_ACCESS_2_TRANSFER_WRITE_BIT;
dst_stage = VK_PIPELINE_STAGE_2_FRAGMENT_SHADER_BIT;
dst_access = VK_ACCESS_2_SHADER_SAMPLED_READ_BIT;
}
else
{
printf("Unknown layout transition\n");
return false;
}
#undef _is_layout_pair
VkImageMemoryBarrier2 barrier{
.sType = VK_STRUCTURE_TYPE_IMAGE_MEMORY_BARRIER_2,
.srcStageMask = src_stage,
.srcAccessMask = src_access,
.dstStageMask = dst_stage,
.dstAccessMask = dst_access,
.oldLayout = old_layout,
.newLayout = new_layout,
.srcQueueFamilyIndex = VK_QUEUE_FAMILY_IGNORED,
.dstQueueFamilyIndex = VK_QUEUE_FAMILY_IGNORED,
.image = image,
.subresourceRange =
{
.aspectMask = aspect,
.baseMipLevel = base_mip_level,
.levelCount = level_count,
.baseArrayLayer = base_array_layer,
.layerCount = layer_count,
},
};
VkDependencyInfo dep_info{
.sType = VK_STRUCTURE_TYPE_DEPENDENCY_INFO,
.imageMemoryBarrierCount = 1,
.pImageMemoryBarriers = &barrier,
};
vkCmdPipelineBarrier2(cmd, &dep_info);
return true;
}
bool Image::load_rgba_from_file(const std::string& path, std::vector<uint8_t>& pixels, VkExtent2D& extent)
{
int w, h, n;
const auto pixel_data = stbi_load(path.c_str(), &w, &h, &n, STBI_rgb_alpha);
if (!pixel_data)
return false;
extent.width = (uint32_t)w;
extent.height = (uint32_t)h;
pixels.resize(w * h * 4);
memcpy(pixels.data(), pixel_data, pixels.size());
stbi_image_free(pixel_data);
return true;
}
bool Image::is_depth_format(VkFormat format)
{
switch(format)
{
case VK_FORMAT_D16_UNORM:
case VK_FORMAT_D32_SFLOAT:
case VK_FORMAT_D16_UNORM_S8_UINT:
case VK_FORMAT_D24_UNORM_S8_UINT:
case VK_FORMAT_D32_SFLOAT_S8_UINT:
return true;
default:
return false;
}
}Show shader_data_table.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#pragma once

#include "image.hpp"

class Pipeline;

class ShaderDataTable
{
public:
    struct EntryDescription
    {
        std::string name{};
        uint32_t set{};
        uint32_t binding{};
        VkDescriptorType type{};
        uint32_t count{};
        VkShaderStageFlags stages{};
    };

public:
    static Result<Box<ShaderDataTable>> create(VkDevice device, std::span<const EntryDescription> entries);

    ShaderDataTable(const ShaderDataTable&) = delete;
    ~ShaderDataTable();

    bool write_image_entry(const std::string& name, const Image* image, VkSampler sampler, uint32_t index = 0);
    bool write_buffer_entry(const std::string& name, const Buffer* buffer, VkDeviceSize offset = 0, VkDeviceSize size = 0, uint32_t index = 0);
    void flush_writes();

    void bind(VkCommandBuffer cmd);

    VkPipelineLayout get_pipeline_layout() const { return m_pipeline_layout; }

protected:
    ShaderDataTable(VkDevice device): m_device(device) {}

private:
    VkDevice m_device{};

    VkDescriptorPool m_pool{};
    VkPipelineLayout m_pipeline_layout{};
    std::vector<VkDescriptorSet> m_sets{};
    std::vector<VkDescriptorSetLayout> m_set_layouts{};
    std::map<std::string, std::pair<uint32_t, uint32_t>> m_entry_map{};

    std::vector<VkWriteDescriptorSet> m_queued_writes{};
    std::deque<VkDescriptorImageInfo> m_queued_write_image_infos{};
    std::deque<VkDescriptorBufferInfo> m_queued_write_buffer_infos{};
};```

</details>

<details>
<summary>Show shader_data_table.cpp</summary>

```cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#include "shader_data_table.hpp"

Result<Box<ShaderDataTable>> ShaderDataTable::create(VkDevice device, std::span<const EntryDescription> entries)
{
    Box<ShaderDataTable> table{new ShaderDataTable(device)};

    uint32_t set_count{};
    for(const auto& entry: entries) {
      set_count = std::max(entry.set + 1, set_count);
    }

    std::map<VkDescriptorType, uint32_t> descriptor_counts{};
    std::vector<std::vector<VkDescriptorSetLayoutBinding>> bindings{set_count};
    for(const auto& entry: entries) {
      bindings[entry.set].push_back({
        .binding = entry.binding,
        .descriptorType = entry.type,
        .descriptorCount = entry.count,
        .stageFlags = entry.stages,
      });

      descriptor_counts[entry.type] += entry.count;

      table->m_entry_map[entry.name] = {entry.set, entry.binding};
    }

    table->m_set_layouts.resize(set_count);
    for(uint32_t i = 0; i < set_count; i++) {
      VkDescriptorSetLayoutCreateInfo set_layout_create_info{
        .sType = VK_STRUCTURE_TYPE_DESCRIPTOR_SET_LAYOUT_CREATE_INFO,
        .bindingCount = (uint32_t)bindings[i].size(),
        .pBindings = bindings[i].data(),
      };

      if (vkCreateDescriptorSetLayout(device, &set_layout_create_info, nullptr, &table->m_set_layouts[i]) != VK_SUCCESS)
        return "Failed to create the descriptor set layout";
    }

    VkPipelineLayoutCreateInfo layout_create_info{
      .sType = VK_STRUCTURE_TYPE_PIPELINE_LAYOUT_CREATE_INFO,
      .setLayoutCount = (uint32_t)table->m_set_layouts.size(),
      .pSetLayouts = table->m_set_layouts.data(),
      .pushConstantRangeCount = 0, // we'll talk about push constants in another post
    };

    if (vkCreatePipelineLayout(device, &layout_create_info, nullptr, &table->m_pipeline_layout) != VK_SUCCESS)
      return "Failed to create the pipeline layout";

    std::vector<VkDescriptorPoolSize> pool_sizes{};
    for(const auto& dc: descriptor_counts) {
      pool_sizes.push_back({.type = dc.first, .descriptorCount = dc.second});
    }

    VkDescriptorPoolCreateInfo pool_create_info{
      .sType = VK_STRUCTURE_TYPE_DESCRIPTOR_POOL_CREATE_INFO,
      .maxSets = set_count,
      .poolSizeCount = (uint32_t)pool_sizes.size(),
      .pPoolSizes = pool_sizes.data(),
    };

    if (vkCreateDescriptorPool(device, &pool_create_info, nullptr, &table->m_pool) != VK_SUCCESS)
      return "Failed to create the descriptor pool";

    table->m_sets.resize(set_count);
    VkDescriptorSetAllocateInfo alloc_info{
        .sType = VK_STRUCTURE_TYPE_DESCRIPTOR_SET_ALLOCATE_INFO,
        .descriptorPool = table->m_pool,
        .descriptorSetCount = (uint32_t)table->m_set_layouts.size(),
        .pSetLayouts = table->m_set_layouts.data(),
    };

    if (vkAllocateDescriptorSets(device, &alloc_info, table->m_sets.data()) != VK_SUCCESS)
      return "Failed to allocate descriptor sets";

    return table;
}

ShaderDataTable::~ShaderDataTable()
{
    if (!m_device)
        return;

    for (size_t i = 0; i < m_set_layouts.size(); i++)
      vkDestroyDescriptorSetLayout(m_device, m_set_layouts[i], nullptr);
    m_set_layouts.clear();

    if (m_pool) vkDestroyDescriptorPool(m_device, m_pool, nullptr);

    if (m_pipeline_layout) vkDestroyPipelineLayout(m_device, m_pipeline_layout, nullptr);
}

bool ShaderDataTable::write_image_entry(const std::string& name, const Image* image, VkSampler sampler, uint32_t index)
{
    const auto entry = m_entry_map.find(name);
    if (entry == m_entry_map.end())
        return false;

    m_queued_write_image_infos.push_back(VkDescriptorImageInfo{
      sampler,
      image->get_view(),
      image->get_layout(),
    });

    m_queued_writes.push_back({
        .sType = VK_STRUCTURE_TYPE_WRITE_DESCRIPTOR_SET,
        .dstSet = m_sets[entry->second.first],
        .dstBinding = entry->second.second,
        .dstArrayElement = index,
        .descriptorCount = 1,
        .descriptorType = VK_DESCRIPTOR_TYPE_COMBINED_IMAGE_SAMPLER,
        .pImageInfo = &m_queued_write_image_infos.back(),
    });

    return true;
}

bool ShaderDataTable::write_buffer_entry(const std::string& name, const Buffer* buffer, VkDeviceSize offset, VkDeviceSize size, uint32_t index)
{
    const auto entry = m_entry_map.find(name);
    if (entry == m_entry_map.end())
        return false;

    m_queued_write_buffer_infos.push_back(VkDescriptorBufferInfo{
        buffer->get_handle(),
        offset,
        (size == 0) ? buffer->get_size() : size,
    });

    m_queued_writes.push_back({
        .sType = VK_STRUCTURE_TYPE_WRITE_DESCRIPTOR_SET,
        .dstSet = m_sets[entry->second.first],
        .dstBinding = entry->second.second,
        .dstArrayElement = index,
        .descriptorCount = 1,
        .descriptorType = VK_DESCRIPTOR_TYPE_UNIFORM_BUFFER, // for now we assume all writes are uniform buffers
        .pBufferInfo = &m_queued_write_buffer_infos.back(),
    });

    return true;
}

void ShaderDataTable::flush_writes()
{
    if (m_queued_writes.empty())
        return;

    vkUpdateDescriptorSets(m_device, m_queued_writes.size(), m_queued_writes.data(), 0, nullptr);

    m_queued_write_image_infos.clear();
    m_queued_write_buffer_infos.clear();

    m_queued_writes.clear();
}

void ShaderDataTable::bind(VkCommandBuffer cmd)
{
    vkCmdBindDescriptorSets(cmd, VK_PIPELINE_BIND_POINT_GRAPHICS, m_pipeline_layout, 0, m_sets.size(), m_sets.data(), 0, nullptr);
}
Show pipeline.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#pragma once

#include "shader_data_table.hpp"

class Pipeline
{
public:
    static Result<Box<Pipeline>> create(VkDevice device,
        VkFormat color_attachment_format,
        VkFormat depth_attachment_format,
        std::span<const VkVertexInputBindingDescription> input_bindings,
        std::span<const VkVertexInputAttributeDescription> input_attributes,
        const ShaderDataTable* data_table,
        std::span<const uint32_t> vertex_shader_source, std::span<const uint32_t> fragment_shader_source);

    Pipeline(const Pipeline&) = delete;
    ~Pipeline();

    void bind(VkCommandBuffer cmd);

protected:
    Pipeline(VkDevice device): m_device(device) {}

private:
    VkDevice m_device{};

    VkPipeline m_handle{};
};```

</details>

<details>
<summary>Show pipeline.cpp</summary>

```cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#include "pipeline.hpp"

Result<Box<Pipeline>> Pipeline::create(VkDevice device,
        VkFormat color_attachment_format,
        VkFormat depth_attachment_format,
        std::span<const VkVertexInputBindingDescription> input_bindings,
        std::span<const VkVertexInputAttributeDescription> input_attributes,
        const ShaderDataTable* data_table,
        std::span<const uint32_t> vertex_shader_source, std::span<const uint32_t> fragment_shader_source)
{
  Box<Pipeline> pipeline{new Pipeline(device)};

  VkShaderModule shader_modules[2];

  VkShaderModuleCreateInfo shader_module_create_infos[2] = {
    {
      .sType = VK_STRUCTURE_TYPE_SHADER_MODULE_CREATE_INFO,
      .codeSize = vertex_shader_source.size() << 2,
      .pCode = vertex_shader_source.data(),
    },
    {
      .sType = VK_STRUCTURE_TYPE_SHADER_MODULE_CREATE_INFO,
      .codeSize = fragment_shader_source.size() << 2,
      .pCode = fragment_shader_source.data(),
    },
  };

  if (vkCreateShaderModule(device, &shader_module_create_infos[0], nullptr, &shader_modules[0]) != VK_SUCCESS)
    return "Failed to create the shader module for vertex shader";

  if (vkCreateShaderModule(device, &shader_module_create_infos[1], nullptr, &shader_modules[1]) != VK_SUCCESS) {
    vkDestroyShaderModule(device, shader_modules[0], nullptr);
    return "Failed to create the shader module for fragment shader";
  }

  VkPipelineShaderStageCreateInfo shader_stage_create_infos[2] = {
    {
      .sType = VK_STRUCTURE_TYPE_PIPELINE_SHADER_STAGE_CREATE_INFO,
      .stage = VK_SHADER_STAGE_VERTEX_BIT,
      .module = shader_modules[0],
      .pName = "main",
    },
    {
      .sType = VK_STRUCTURE_TYPE_PIPELINE_SHADER_STAGE_CREATE_INFO,
      .stage = VK_SHADER_STAGE_FRAGMENT_BIT,
      .module = shader_modules[1],
      .pName = "main",
    },
  };

  VkPipelineRenderingCreateInfo rendering_create_info {
    .sType = VK_STRUCTURE_TYPE_PIPELINE_RENDERING_CREATE_INFO,
    .colorAttachmentCount = 1,
    .pColorAttachmentFormats = &color_attachment_format,
    .depthAttachmentFormat = depth_attachment_format,
    .stencilAttachmentFormat = VK_FORMAT_UNDEFINED,
  };

  VkPipelineVertexInputStateCreateInfo vertex_input_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_VERTEX_INPUT_STATE_CREATE_INFO,
    .vertexBindingDescriptionCount = (uint32_t)input_bindings.size(),
    .pVertexBindingDescriptions = input_bindings.data(),
    .vertexAttributeDescriptionCount = (uint32_t)input_attributes.size(),
    .pVertexAttributeDescriptions = input_attributes.data(),
  };

  VkPipelineInputAssemblyStateCreateInfo ia_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_INPUT_ASSEMBLY_STATE_CREATE_INFO,
    .topology = VK_PRIMITIVE_TOPOLOGY_TRIANGLE_LIST,
  };

  VkPipelineViewportStateCreateInfo viewport_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_VIEWPORT_STATE_CREATE_INFO,
    .viewportCount = 1,
    .scissorCount = 1,
  };

  VkPipelineRasterizationStateCreateInfo rs_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_RASTERIZATION_STATE_CREATE_INFO,
    .polygonMode = VK_POLYGON_MODE_FILL,
    .cullMode = VK_CULL_MODE_NONE,
    .lineWidth = 1.0,
  };

  VkPipelineMultisampleStateCreateInfo multisample_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_MULTISAMPLE_STATE_CREATE_INFO,
    .rasterizationSamples = VK_SAMPLE_COUNT_1_BIT,
  };

  VkPipelineColorBlendAttachmentState color_blend_attachment_state{
    .blendEnable = VK_FALSE,
    .colorWriteMask = VK_COLOR_COMPONENT_R_BIT | VK_COLOR_COMPONENT_G_BIT |
                  VK_COLOR_COMPONENT_B_BIT | VK_COLOR_COMPONENT_A_BIT,
  };

  VkPipelineColorBlendStateCreateInfo color_blend_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_COLOR_BLEND_STATE_CREATE_INFO,
    .attachmentCount = 1,
    .pAttachments = &color_blend_attachment_state,
  };

  VkDynamicState dynamic_states[2] = {
    VK_DYNAMIC_STATE_VIEWPORT,
    VK_DYNAMIC_STATE_SCISSOR,
  };

  VkPipelineDynamicStateCreateInfo dynamic_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_DYNAMIC_STATE_CREATE_INFO,
    .dynamicStateCount = (sizeof(dynamic_states)/sizeof(dynamic_states[0])),
    .pDynamicStates = dynamic_states,
  };

  VkPipelineDepthStencilStateCreateInfo depth_stencil_state_create_info{
    .sType = VK_STRUCTURE_TYPE_PIPELINE_DEPTH_STENCIL_STATE_CREATE_INFO,
    .depthTestEnable = true,
    .depthWriteEnable = true,
    .depthCompareOp = VK_COMPARE_OP_LESS,
    .minDepthBounds = 0.0f,
    .maxDepthBounds = 1.0f,
  };

  VkGraphicsPipelineCreateInfo create_info{
    .sType = VK_STRUCTURE_TYPE_GRAPHICS_PIPELINE_CREATE_INFO,
    .pNext = &rendering_create_info,

    .stageCount = (sizeof(shader_stage_create_infos)/sizeof(shader_stage_create_infos[0])),
    .pStages = shader_stage_create_infos,

    .pVertexInputState = &vertex_input_state_create_info,
    .pInputAssemblyState = &ia_state_create_info,
    .pViewportState = &viewport_state_create_info,
    .pRasterizationState = &rs_create_info,
    .pMultisampleState = &multisample_state_create_info,
    .pDepthStencilState = &depth_stencil_state_create_info,
    .pColorBlendState = &color_blend_state_create_info,
    .pDynamicState = &dynamic_state_create_info,

    .layout = data_table->get_pipeline_layout(),
  };

  if (vkCreateGraphicsPipelines(device, nullptr, 1, &create_info, nullptr, &pipeline->m_handle) != VK_SUCCESS) {
    vkDestroyShaderModule(device, shader_modules[0], nullptr);
    vkDestroyShaderModule(device, shader_modules[1], nullptr);

    return "Failed to create the graphics pipeline";
  }

  vkDestroyShaderModule(device, shader_modules[0], nullptr);
  vkDestroyShaderModule(device, shader_modules[1], nullptr);

  return pipeline;
}

void Pipeline::bind(VkCommandBuffer cmd)
{
  // for now we'll only be using graphics pipeline so we can just hardcode VK_PIPELINE_BIND_POINT_GRAPHICS here
  vkCmdBindPipeline(cmd, VK_PIPELINE_BIND_POINT_GRAPHICS, m_handle);
}

Pipeline::~Pipeline()
{
  if (!m_device)
    return;

  if (m_handle) vkDestroyPipeline(m_device, m_handle, nullptr);
}
Show sample.hpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#pragma once

#include "image.hpp"
#include "buffer.hpp"
#include "pipeline.hpp"

#include <vector>
#include <string>
#include <cassert>
#include <stdint.h>
#include <functional>

class SampleVulkan
{
  static constexpr uint32_t NUM_CONCURRENT_FRAMES = 3;
  static constexpr const char *VALIDATION_LAYER_NAME = "VK_LAYER_KHRONOS_validation";
  static constexpr const char *SWAPCHAIN_DEVICE_EXTENSION_NAME = "VK_KHR_swapchain";
  static constexpr const char *PORTABILITY_SUBSET_DEVICE_EXTENSION_NAME = "VK_KHR_portability_subset";

  struct FrameResourceSet
  {
    VkFence fen_in_flight{};
    VkSemaphore sm_image_available{};
    VkCommandBuffer cmd_buffer{};
  };

public:
  SampleVulkan() = default;
  SampleVulkan(const SampleVulkan &) = delete;
  SampleVulkan &operator=(const SampleVulkan &) = delete;

  ~SampleVulkan();

  bool initialize(std::function<bool(VkInstance, uint32_t &, uint32_t &, VkSurfaceKHR &)> surface_creation_callback);

  bool render();

  void resize(uint32_t fb_width, uint32_t fb_height);

private:
  bool create_instance();
  bool select_physical_device();
  bool create_device_and_swapchain();
  bool create_frame_resources();

  void draw_frame(VkCommandBuffer cmd, VkImageView color_attachment);

  bool execute_single_shot_commands(std::function<Result<>(VkCommandBuffer)> commands);

  bool recreate_swapchain();

private:
  VkInstance m_instance{};
  VkDebugUtilsMessengerEXT m_debug_messenger{};

  VkSurfaceKHR m_surface{};
  std::string m_physical_device_name{};
  VkPhysicalDevice m_physical_device{};
  uint32_t m_graphics_queue_family_index{};
  uint32_t m_present_queue_family_index{};
  uint32_t m_swapchain_image_count{};
  std::vector<VkSemaphore> m_render_done_semaphores;
  VkSurfaceFormatKHR m_swapchain_format{};
  VkPresentModeKHR m_swapchain_present_mode{};
  VkExtent2D m_swapchain_extent{1, 1};
  VkExtent2D m_pending_swapchain_extent{1, 1};
  bool m_swapchain_is_out_of_date{};
  VkSurfaceTransformFlagBitsKHR m_swapchain_pre_transform{};
  Box<Image> m_depth_attachment{};

  VkDevice m_device{};
  VkQueue m_graphics_queue{};
  VkQueue m_present_queue{};
  VkSwapchainKHR m_swapchain{};
  std::vector<VkImage> m_swapchain_images{};
  std::vector<VkImageView> m_swapchain_image_views{};

  uint32_t m_current_frame_index{};
  VkCommandPool m_frame_resource_command_pool{};
  FrameResourceSet m_frames[NUM_CONCURRENT_FRAMES];

  Box<Pipeline> m_graphics_pipeline{};

  VmaAllocator m_allocator{};

  Box<Buffer> m_staging_buffer{};
  Box<Buffer> m_vertex_buffer{};
  Box<Buffer> m_index_buffer{};
  Box<Buffer> m_vertex_uniform_buffer{};

  VkFence m_single_shot_command_fence{};
  VkCommandPool m_single_shot_command_pool{};
  VkCommandBuffer m_single_shot_command_buffer{};

  Box<Image> m_texture_image{};
  VkSampler m_texture_sampler{};

  Box<ShaderDataTable> m_shader_data_table{};
};
Show sample.cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.
#include "sample.hpp"
#include <set>
#include <chrono>
#include <stdio.h>
#include <string.h>
#include <utility>
#include <fstream>
#include <algorithm>
template<typename ElementT, typename FuncT, typename... Args> std::vector<ElementT> vkEnumCall(FuncT f, Args... args)
{
uint32_t _count{};
f(args..., &_count, nullptr);
std::vector<ElementT> result(_count);
f(args..., &_count, result.data());
return result;
}
struct Vertex
{
glm::vec3 pos;
glm::vec3 colour;
glm::vec2 texcoord;
};
struct VertexUniformData
{
glm::mat4 model;
glm::mat4 view;
glm::mat4 projection;
} g_vertex_uniform_data;
static const Vertex VERTICES[24] = {
{glm::vec3(-0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3( 0.5f, -0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3( 0.5f, 0.5f, -0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(-0.5f, 0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
{glm::vec3(-0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3( 0.5f, -0.5f, 0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3( 0.5f, 0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(-0.5f, 0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
{glm::vec3( -0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3( -0.5f, 0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3(-0.5f, 0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(-0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
{glm::vec3(0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3(0.5f, 0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3(0.5f, 0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
{glm::vec3(-0.5f, -0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3( 0.5f, -0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3( 0.5f, -0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(-0.5f, -0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
{glm::vec3(-0.5f, 0.5f, -0.5f), glm::vec3(1.0f, 0.0f, 0.0f), glm::vec2(0.0f, 0.0f)},
{glm::vec3( 0.5f, 0.5f, -0.5f), glm::vec3(0.0f, 1.0f, 0.0f) , glm::vec2(1.0f, 0.0f)},
{glm::vec3( 0.5f, 0.5f, 0.5f), glm::vec3(0.0f, 0.0f, 1.0f) , glm::vec2(1.0f, 1.0f)},
{glm::vec3(-0.5f, 0.5f, 0.5f), glm::vec3(1.0f, 0.0f, 1.0f), glm::vec2(0.0f, 1.0f)},
};
static const uint32_t INDICES[36] = {
0, 1, 2,
2, 3, 0,
4, 5, 6,
6, 7, 4,
8, 9, 10,
10, 11, 8,
12, 13, 14,
14, 15, 12,
16, 17, 18,
18, 19, 16,
20, 21, 22,
22, 23, 20,
};
// Create checkerboard pattern pixels (violet and white)
static std::vector<uint8_t> get_checkerboard_pattern_pixels(uint32_t width, uint32_t height, uint32_t checker_size = 4)
{
std::vector<uint8_t> rgba_data(width * height * 4);
for (uint32_t y = 0; y < height; ++y)
{
for (uint32_t x = 0; x < width; ++x)
{
const bool is_violet = ((x / checker_size) % 2) == ((y / checker_size) % 2);
uint32_t index = (y * width + x) * 4;
if (is_violet)
{
rgba_data[index + 0] = 255;
rgba_data[index + 1] = 0;
rgba_data[index + 2] = 255;
rgba_data[index + 3] = 255;
}
else
{
rgba_data[index + 0] = 255;
rgba_data[index + 1] = 255;
rgba_data[index + 2] = 255;
rgba_data[index + 3] = 255;
}
}
}
return rgba_data;
}
static Result<std::vector<uint32_t>> load_shader_from_file(const std::string& path)
{
std::ifstream f(path, std::ios::in | std::ios::binary | std::ios::ate);
if (!f.is_open())
return "Failed to open shader file \""+ path + "\".";
std::vector<uint32_t> data;
data.resize(f.tellg() >> 2);
f.seekg(SEEK_SET);
f.read((char*)data.data(), data.size() << 2);
return std::move(data);
}
SampleVulkan::~SampleVulkan()
{
if (m_device)
{
vkDeviceWaitIdle(m_device);
m_texture_image.reset();
vkDestroySampler(m_device, m_texture_sampler, nullptr);
vkDestroyFence(m_device, m_single_shot_command_fence, nullptr);
vkDestroyCommandPool(m_device, m_single_shot_command_pool, nullptr);
m_graphics_pipeline.reset();
m_shader_data_table.reset();
m_vertex_buffer.reset();
m_index_buffer.reset();
m_staging_buffer.reset();
m_vertex_uniform_buffer.reset();
m_depth_attachment.reset();
for (uint32_t i = 0; i < NUM_CONCURRENT_FRAMES; i++)
{
vkDestroyFence(m_device, m_frames[i].fen_in_flight, nullptr);
vkDestroySemaphore(m_device, m_frames[i].sm_image_available, nullptr);
}
for (size_t i = 0; i < m_render_done_semaphores.size(); i++)
vkDestroySemaphore(m_device, m_render_done_semaphores[i], nullptr);
m_render_done_semaphores.clear();
vkDestroyCommandPool(m_device, m_frame_resource_command_pool, nullptr);
for (const auto &view : m_swapchain_image_views)
vkDestroyImageView(m_device, view, nullptr);
vkDestroySwapchainKHR(m_device, m_swapchain, nullptr);
vmaDestroyAllocator(m_allocator);
vkDestroyDevice(m_device, nullptr);
}
if (m_instance)
{
if (m_surface)
vkDestroySurfaceKHR(m_instance, m_surface, nullptr);
{
const auto debug_messenger_destroy_func =
(PFN_vkDestroyDebugUtilsMessengerEXT) vkGetInstanceProcAddr(m_instance, "vkDestroyDebugUtilsMessengerEXT");
if (debug_messenger_destroy_func && m_debug_messenger)
debug_messenger_destroy_func(m_instance, m_debug_messenger, nullptr);
}
vkDestroyInstance(m_instance, nullptr);
}
}
bool SampleVulkan::initialize(
std::function<bool(VkInstance, uint32_t &, uint32_t &, VkSurfaceKHR &)> surface_creation_callback)
{
if (!create_instance())
return false;
if (!surface_creation_callback(m_instance, m_pending_swapchain_extent.width, m_pending_swapchain_extent.height,
m_surface))
{
printf("Failed to create Vulkan surface\n");
return false;
}
if (!select_physical_device())
return false;
if (!create_device_and_swapchain())
return false;
if (!create_frame_resources())
return false;
CHECK_RESULT(
ShaderDataTable::create(
m_device,
std::initializer_list<ShaderDataTable::EntryDescription>{
{.name = "vertex_uniform_data", .set = 0, .binding = 0, .type = VK_DESCRIPTOR_TYPE_UNIFORM_BUFFER, .count = 1, .stages = VK_SHADER_STAGE_VERTEX_BIT,},
{.name = "texture_sampler", .set = 1, .binding = 0, .type = VK_DESCRIPTOR_TYPE_COMBINED_IMAGE_SAMPLER, .count = 1, .stages = VK_SHADER_STAGE_FRAGMENT_BIT,},
}
),
m_shader_data_table
);
std::vector<uint32_t> vertex_shader_data, fragment_shader_data{};
CHECK_RESULT(load_shader_from_file("resources/default.vert.spv"), vertex_shader_data);
CHECK_RESULT(load_shader_from_file("resources/default.frag.spv"), fragment_shader_data);
CHECK_RESULT(
Pipeline::create(
m_device,
m_swapchain_format.format,
m_depth_attachment->get_format(),
std::initializer_list<VkVertexInputBindingDescription>{
{.binding = 0, .stride = sizeof(Vertex), .inputRate = VK_VERTEX_INPUT_RATE_VERTEX},
},
std::initializer_list<VkVertexInputAttributeDescription>{
VkVertexInputAttributeDescription{.location = 0, .binding = 0, .format = VK_FORMAT_R32G32B32_SFLOAT, .offset = offsetof(Vertex, pos)},
VkVertexInputAttributeDescription{.location = 1, .binding = 0, .format = VK_FORMAT_R32G32B32_SFLOAT, .offset = offsetof(Vertex, colour)},
VkVertexInputAttributeDescription{.location = 2, .binding = 0, .format = VK_FORMAT_R32G32_SFLOAT, .offset = offsetof(Vertex, texcoord)},
},
m_shader_data_table.get(),
vertex_shader_data,
fragment_shader_data
),
m_graphics_pipeline
);
CHECK_RESULT(
Buffer::create(
m_allocator,
std::max(sizeof(VERTICES), sizeof(INDICES)), // maximum size we'll need for our staging operations
Buffer::EUsage::STAGING
),
m_staging_buffer
);
CHECK_RESULT(
Buffer::create(
m_allocator,
sizeof(VERTICES),
Buffer::EUsage::VERTEX
),
m_vertex_buffer
);
CHECK_RESULT(
Buffer::create(
m_allocator,
sizeof(INDICES),
Buffer::EUsage::INDEX
),
m_index_buffer
);
CHECK_RESULT(
Buffer::create(
m_allocator,
sizeof(VertexUniformData),
Buffer::EUsage::UNIFORM
),
m_vertex_uniform_buffer
);
{
g_vertex_uniform_data.model = glm::translate(glm::mat4(1.0f), glm::vec3(0.0f, 0.0f, 0.0f));
g_vertex_uniform_data.view = glm::lookAt(glm::vec3(0.0f, 0.0f, 0.75f), glm::vec3(0.0f, 0.0f, 0.0f), glm::vec3(0.0f, 1.0f, 0.0f));
if (!m_vertex_uniform_buffer->copy_from_cpu(&g_vertex_uniform_data, sizeof(g_vertex_uniform_data))) {
printf("Failed to copy data to uniform buffer\n");
return false;
}
}
{ // copy VERTICES to vertex buffer
if(!m_staging_buffer->copy_from_cpu(VERTICES, sizeof(VERTICES))) {
printf("Failed to copy VERTICES to staging buffer\n");
return false;
}
const auto success = execute_single_shot_commands([&](VkCommandBuffer cmd) -> Result<>
{
VkBufferCopy copy_region{
.srcOffset = 0,
.dstOffset = 0,
.size = m_vertex_buffer->get_size(),
};
vkCmdCopyBuffer(cmd, m_staging_buffer->get_handle(), m_vertex_buffer->get_handle(), 1, ©_region);
VkMemoryBarrier barrier{
.sType = VK_STRUCTURE_TYPE_MEMORY_BARRIER,
.srcAccessMask = VK_ACCESS_TRANSFER_WRITE_BIT,
.dstAccessMask = VK_ACCESS_VERTEX_ATTRIBUTE_READ_BIT,
};
vkCmdPipelineBarrier(cmd, VK_PIPELINE_STAGE_TRANSFER_BIT, VK_PIPELINE_STAGE_VERTEX_INPUT_BIT,
0, 1, &barrier, 0, nullptr, 0, nullptr);
return Ok{};
});
if(!success) {
printf("Failed to copy staging buffer to vertex buffer\n");
return false;
}
}
{ // copy INDICES to index buffer
if(!m_staging_buffer->copy_from_cpu(INDICES, sizeof(INDICES))) {
printf("Failed to copy INDICES to staging buffer\n");
return false;
}
const auto success = execute_single_shot_commands([&](VkCommandBuffer cmd) -> Result<>
{
VkBufferCopy copy_region{
.srcOffset = 0,
.dstOffset = 0,
.size = m_index_buffer->get_size(),
};
vkCmdCopyBuffer(cmd, m_staging_buffer->get_handle(), m_index_buffer->get_handle(), 1, ©_region);
VkMemoryBarrier barrier{
.sType = VK_STRUCTURE_TYPE_MEMORY_BARRIER,
.srcAccessMask = VK_ACCESS_TRANSFER_WRITE_BIT,
.dstAccessMask = VK_ACCESS_INDEX_READ_BIT,
};
vkCmdPipelineBarrier(cmd, VK_PIPELINE_STAGE_TRANSFER_BIT, VK_PIPELINE_STAGE_VERTEX_INPUT_BIT,
0, 1, &barrier, 0, nullptr, 0, nullptr);
return Ok{};
});
if (!success) {
printf("Failed to copy staging buffer to index buffer\n");
return false;
}
}
{
VkSamplerCreateInfo create_info{
.sType = VK_STRUCTURE_TYPE_SAMPLER_CREATE_INFO,
.magFilter = VK_FILTER_LINEAR,
.minFilter = VK_FILTER_LINEAR,
.addressModeU = VK_SAMPLER_ADDRESS_MODE_REPEAT,
.addressModeV = VK_SAMPLER_ADDRESS_MODE_REPEAT,
.addressModeW = VK_SAMPLER_ADDRESS_MODE_REPEAT,
};
if (vkCreateSampler(m_device, &create_info, nullptr, &m_texture_sampler) != VK_SUCCESS) {
printf("Failed to create the texture sampler\n");
return false;
}
}
{
std::vector<uint8_t> pixels{};
VkExtent2D extent{};
if (!Image::load_rgba_from_file("resources/Ground037_1K-PNG_Color.png", pixels, extent)) {
printf("Failed to load texture data from the disk\n");
return false;
}
CHECK_RESULT(
Image::create(
m_device,
m_allocator,
VK_FORMAT_R8G8B8A8_SRGB,
extent,
VK_IMAGE_USAGE_SAMPLED_BIT | VK_IMAGE_USAGE_TRANSFER_DST_BIT // We want to sample this image from fragment shader and
// copy data from staging buffer into this image.
),
m_texture_image);
const auto success = execute_single_shot_commands([&](VkCommandBuffer cmd) -> Result<>
{
if (!m_texture_image->transition_layout(cmd, VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL))
return "Failed to transition texture image to VK_IMAGE_LAYOUT_TRANSFER_DST_OPTIMAL";
if (!m_texture_image->copy_from_cpu(cmd, pixels.data(), pixels.size()))
return "Failed to copy pixels to texture image";
if (!m_texture_image->transition_layout(cmd, VK_IMAGE_LAYOUT_SHADER_READ_ONLY_OPTIMAL))
return "Failed to transition texture image to VK_IMAGE_LAYOUT_SHADER_READ_ONLY_OPTIMAL";
return Ok{};
});
if (!success) {
printf("Failed to copy pixels to the image\n");
return false;
}
}
if (!m_shader_data_table->write_buffer_entry("vertex_uniform_data", m_vertex_uniform_buffer.get())) {
printf("Failed to write uniform buffer to shader data table\n");
return false;
}
if (!m_shader_data_table->write_image_entry("texture_sampler", m_texture_image.get(), m_texture_sampler)) {
printf("Failed to write texture image to shader data table\n");
return false;
}
m_shader_data_table->flush_writes();
return true;
}
bool SampleVulkan::render()
{
const auto ¤t_frame = m_frames[m_current_frame_index];
vkWaitForFences(m_device, 1, ¤t_frame.fen_in_flight, VK_TRUE, UINT64_MAX);
uint32_t image_index{};
switch (vkAcquireNextImageKHR(m_device, m_swapchain, UINT64_MAX, current_frame.sm_image_available, VK_NULL_HANDLE,
&image_index))
{
case VK_ERROR_OUT_OF_DATE_KHR:
if (!recreate_swapchain())
return false;
return true;
case VK_SUCCESS:
case VK_SUBOPTIMAL_KHR:
break;
default:
printf("Failed to acquire swapchain image\n");
return false;
}
VkCommandBufferBeginInfo cmd_begin_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_BUFFER_BEGIN_INFO,
};
vkResetCommandBuffer(current_frame.cmd_buffer, 0);
if (vkBeginCommandBuffer(current_frame.cmd_buffer, &cmd_begin_info) != VK_SUCCESS)
{
printf("Failed to start recording command buffer\n");
return false;
}
if (!Image::transition_image_layout(current_frame.cmd_buffer, m_swapchain_images[image_index], VK_IMAGE_LAYOUT_UNDEFINED,
VK_IMAGE_LAYOUT_COLOR_ATTACHMENT_OPTIMAL))
{
printf("Failed to transition swapchain image\n");
return false;
}
draw_frame(current_frame.cmd_buffer, m_swapchain_image_views[image_index]);
if (!Image::transition_image_layout(current_frame.cmd_buffer, m_swapchain_images[image_index],
VK_IMAGE_LAYOUT_COLOR_ATTACHMENT_OPTIMAL, VK_IMAGE_LAYOUT_PRESENT_SRC_KHR))
{
printf("Failed to transition swapchain image\n");
return false;
}
if (vkEndCommandBuffer(current_frame.cmd_buffer) != VK_SUCCESS)
{
printf("Failed to finish recording command buffer\n");
return false;
}
VkPipelineStageFlags submit_pipeline_wait_stage{VK_PIPELINE_STAGE_COLOR_ATTACHMENT_OUTPUT_BIT};
VkSubmitInfo submit_info{
.sType = VK_STRUCTURE_TYPE_SUBMIT_INFO,
.waitSemaphoreCount = 1,
.pWaitSemaphores = ¤t_frame.sm_image_available,
.pWaitDstStageMask = &submit_pipeline_wait_stage,
.commandBufferCount = 1,
.pCommandBuffers = ¤t_frame.cmd_buffer,
.signalSemaphoreCount = 1,
.pSignalSemaphores = &m_render_done_semaphores[image_index],
};
vkResetFences(m_device, 1, ¤t_frame.fen_in_flight);
if (vkQueueSubmit(m_graphics_queue, 1, &submit_info, current_frame.fen_in_flight) != VK_SUCCESS)
{
printf("Failed to submit frame command buffer\n");
return false;
}
VkPresentInfoKHR present_info{
.sType = VK_STRUCTURE_TYPE_PRESENT_INFO_KHR,
.waitSemaphoreCount = 1,
.pWaitSemaphores = &m_render_done_semaphores[image_index],
.swapchainCount = 1,
.pSwapchains = &m_swapchain,
.pImageIndices = &image_index,
};
switch (vkQueuePresentKHR(m_present_queue, &present_info))
{
case VK_ERROR_OUT_OF_DATE_KHR:
case VK_SUBOPTIMAL_KHR:
if (!recreate_swapchain())
return false;
break;
case VK_SUCCESS:
break;
default:
printf("Failed to present swapchain\n");
return false;
}
if (m_swapchain_is_out_of_date && !recreate_swapchain())
return false;
m_current_frame_index = (m_current_frame_index + 1) % NUM_CONCURRENT_FRAMES;
return true;
}
void SampleVulkan::draw_frame(VkCommandBuffer cmd, VkImageView color_attachment)
{
{
static constexpr float SPEED = glm::radians(90.0f);
static auto start_time = std::chrono::steady_clock::now();
const auto current_time = std::chrono::steady_clock::now();
const auto seconds = std::chrono::duration<float>(current_time - start_time).count();
g_vertex_uniform_data.model =
glm::rotate(glm::mat4(1.0f), std::fmod(seconds * SPEED, glm::two_pi<float>()), glm::vec3(1.0f, 1.0f, 1.0f))
* glm::scale(glm::mat4(1.0f), glm::vec3(0.25f));
m_vertex_uniform_buffer->copy_from_cpu(&g_vertex_uniform_data, sizeof(g_vertex_uniform_data));
}
VkRenderingAttachmentInfo color_attachment_info{
.sType = VK_STRUCTURE_TYPE_RENDERING_ATTACHMENT_INFO,
.imageView = color_attachment,
.imageLayout = VK_IMAGE_LAYOUT_COLOR_ATTACHMENT_OPTIMAL,
.loadOp = VK_ATTACHMENT_LOAD_OP_CLEAR,
.storeOp = VK_ATTACHMENT_STORE_OP_STORE,
.clearValue =
{
.color =
{
0.1f,
0.1f,
0.1f,
1.0f,
},
},
};
VkRenderingAttachmentInfo depth_attachment_info{
.sType = VK_STRUCTURE_TYPE_RENDERING_ATTACHMENT_INFO,
.imageView = m_depth_attachment->get_view(),
.imageLayout = VK_IMAGE_LAYOUT_DEPTH_ATTACHMENT_OPTIMAL,
.loadOp = VK_ATTACHMENT_LOAD_OP_CLEAR,
.storeOp = VK_ATTACHMENT_STORE_OP_DONT_CARE,
.clearValue =
{
.depthStencil =
{
1.0f,
0,
},
},
};
VkRenderingInfo rendering_info{
.sType = VK_STRUCTURE_TYPE_RENDERING_INFO,
.renderArea =
{
{},
m_swapchain_extent,
},
.layerCount = 1,
.viewMask = 0,
.colorAttachmentCount = 1,
.pColorAttachments = &color_attachment_info,
.pDepthAttachment = &depth_attachment_info,
};
vkCmdBeginRendering(cmd, &rendering_info);
VkViewport viewport = {
.width = (float)m_swapchain_extent.width,
.height = (float)m_swapchain_extent.height,
.minDepth = 0.0f,
.maxDepth = 1.0f,
};
vkCmdSetViewport(cmd, 0, 1, &viewport);
VkRect2D scissor{
.extent = m_swapchain_extent,
};
vkCmdSetScissor(cmd, 0, 1, &scissor);
m_graphics_pipeline->bind(cmd);
m_vertex_buffer->bind(cmd);
m_index_buffer->bind(cmd);
m_shader_data_table->bind(cmd);
vkCmdDrawIndexed(cmd, sizeof(INDICES)/sizeof(INDICES[0]), 1, 0, 0, 0);
vkCmdEndRendering(cmd);
}
bool SampleVulkan::execute_single_shot_commands(std::function<Result<>(VkCommandBuffer)> commands)
{
if (vkResetCommandBuffer(m_single_shot_command_buffer, 0) != VK_SUCCESS)
return false;
VkCommandBufferBeginInfo begin_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_BUFFER_BEGIN_INFO,
};
if (vkBeginCommandBuffer(m_single_shot_command_buffer, &begin_info) != VK_SUCCESS)
return false;
const auto result = commands(m_single_shot_command_buffer);
if (result.is_error()) {
printf("%s\n", result.get_error().c_str());
return false;
}
if (vkEndCommandBuffer(m_single_shot_command_buffer) != VK_SUCCESS)
return false;
VkSubmitInfo submit_info{
.sType = VK_STRUCTURE_TYPE_SUBMIT_INFO,
.commandBufferCount = 1,
.pCommandBuffers = &m_single_shot_command_buffer,
};
if (vkQueueSubmit(m_graphics_queue, 1, &submit_info, m_single_shot_command_fence) != VK_SUCCESS)
return false;
if (vkWaitForFences(m_device, 1, &m_single_shot_command_fence, true, UINT64_MAX) != VK_SUCCESS)
return false;
if (vkResetFences(m_device, 1, &m_single_shot_command_fence) != VK_SUCCESS)
return false;
return true;
}
bool SampleVulkan::create_instance()
{
// This is a sample, not production code, so we always enable validation layers,
// unless they're unavailable
const auto instance_layer_props = vkEnumCall<VkLayerProperties>(vkEnumerateInstanceLayerProperties);
const bool enable_validation_layers =
std::any_of(instance_layer_props.begin(), instance_layer_props.end(),
[](VkLayerProperties p) { return strcmp(p.layerName, VALIDATION_LAYER_NAME) == 0; });
VkDebugUtilsMessengerCreateInfoEXT debug_messenger_create_info{
.sType = VK_STRUCTURE_TYPE_DEBUG_UTILS_MESSENGER_CREATE_INFO_EXT,
.messageSeverity =
VK_DEBUG_UTILS_MESSAGE_SEVERITY_WARNING_BIT_EXT | VK_DEBUG_UTILS_MESSAGE_SEVERITY_ERROR_BIT_EXT,
.messageType = VK_DEBUG_UTILS_MESSAGE_TYPE_GENERAL_BIT_EXT | VK_DEBUG_UTILS_MESSAGE_TYPE_VALIDATION_BIT_EXT |
VK_DEBUG_UTILS_MESSAGE_TYPE_PERFORMANCE_BIT_EXT,
.pfnUserCallback = [](VkDebugUtilsMessageSeverityFlagBitsEXT severity, VkDebugUtilsMessageTypeFlagsEXT type,
const VkDebugUtilsMessengerCallbackDataEXT *callback_data, void *user_data) -> VkBool32 {
printf("[VK_VALIDATION_LAYER]: %s\n", callback_data->pMessage);
return VK_FALSE;
},
};
std::vector<const char *> extensions;
{ // GLFW Extensions
uint32_t glfw_ext_count{};
const auto glfw_ext = glfwGetRequiredInstanceExtensions(&glfw_ext_count);
extensions.insert(extensions.end(), glfw_ext, glfw_ext + glfw_ext_count);
}
if (enable_validation_layers)
extensions.push_back(VK_EXT_DEBUG_UTILS_EXTENSION_NAME);
// macOS support: MoltenVK is a "portability" implementation (it doesn't support all
// of Vulkan), so the loader only exposes it to us if we explicitly opt in.
const auto instance_ext_props = vkEnumCall<VkExtensionProperties>(vkEnumerateInstanceExtensionProperties, nullptr);
const bool enable_portability =
std::any_of(instance_ext_props.begin(), instance_ext_props.end(), [](VkExtensionProperties p) {
return strcmp(p.extensionName, VK_KHR_PORTABILITY_ENUMERATION_EXTENSION_NAME) == 0;
});
if (enable_portability)
extensions.push_back(VK_KHR_PORTABILITY_ENUMERATION_EXTENSION_NAME);
VkApplicationInfo app_info{
.sType = VK_STRUCTURE_TYPE_APPLICATION_INFO,
.pApplicationName = "i-a-s.me Vulkan 1.3 Sample",
.applicationVersion = VK_MAKE_VERSION(1, 0, 0),
.pEngineName = "i-a-s.me Vulkan 1.3 Sample",
.engineVersion = VK_MAKE_VERSION(1, 0, 0),
.apiVersion = VK_API_VERSION_1_3,
};
VkInstanceCreateInfo create_info{
.sType = VK_STRUCTURE_TYPE_INSTANCE_CREATE_INFO,
.pNext = enable_validation_layers ? &debug_messenger_create_info : nullptr,
.flags = enable_portability ? (VkInstanceCreateFlags) VK_INSTANCE_CREATE_ENUMERATE_PORTABILITY_BIT_KHR : 0u,
.pApplicationInfo = &app_info,
.enabledLayerCount = enable_validation_layers ? 1u : 0u,
.ppEnabledLayerNames = enable_validation_layers ? &VALIDATION_LAYER_NAME : nullptr,
.enabledExtensionCount = (uint32_t) extensions.size(),
.ppEnabledExtensionNames = extensions.data(),
};
if (vkCreateInstance(&create_info, nullptr, &m_instance) != VK_SUCCESS)
{
printf("Failed to create Vulkan instance\n");
return false;
}
const auto debug_messenger_create_func =
(PFN_vkCreateDebugUtilsMessengerEXT) vkGetInstanceProcAddr(m_instance, "vkCreateDebugUtilsMessengerEXT");
if (enable_validation_layers && debug_messenger_create_func)
{
if (debug_messenger_create_func(m_instance, &debug_messenger_create_info, nullptr, &m_debug_messenger) !=
VK_SUCCESS)
{
printf("Failed to create Vulkan debug messenger\n");
return false;
}
}
return true;
}
bool SampleVulkan::select_physical_device()
{
const auto find_queue_families = [&](VkPhysicalDevice p) -> std::pair<uint32_t, uint32_t> {
uint32_t graphics_family_index{UINT32_MAX}, present_family_index{UINT32_MAX};
const auto queue_families = vkEnumCall<VkQueueFamilyProperties>(vkGetPhysicalDeviceQueueFamilyProperties, p);
for (uint32_t i = 0; i < (uint32_t) queue_families.size(); i++)
{
const auto &f = queue_families[i];
if (f.queueFlags & VK_QUEUE_GRAPHICS_BIT)
graphics_family_index = i;
VkBool32 has_present_support{};
if ((vkGetPhysicalDeviceSurfaceSupportKHR(p, i, m_surface, &has_present_support) == VK_SUCCESS) &&
has_present_support)
present_family_index = i;
if ((graphics_family_index != UINT32_MAX) && (present_family_index != UINT32_MAX))
break;
}
return {graphics_family_index, present_family_index};
};
m_physical_device = VK_NULL_HANDLE;
const auto physical_devices = vkEnumCall<VkPhysicalDevice>(vkEnumeratePhysicalDevices, m_instance);
for (const auto &p : physical_devices)
{
VkPhysicalDeviceProperties2 props{
.sType = VK_STRUCTURE_TYPE_PHYSICAL_DEVICE_PROPERTIES_2,
};
vkGetPhysicalDeviceProperties2(p, &props);
if (props.properties.apiVersion < VK_API_VERSION_1_3)
continue; // If this physical device does not support at least Vulkan 1.3, we cannot use it. We use Vulkan 1.3
// core features in this sample.
const auto queue_family_indices = find_queue_families(p);
if ((queue_family_indices.first == UINT32_MAX) || (queue_family_indices.second == UINT32_MAX))
continue; // This physical device isn't what we want, if it lacks either graphics or present queue families
// We could (and should) do more suitability checks in a real application,
// but for this sample, this is just ok.
m_physical_device = p;
m_graphics_queue_family_index = queue_family_indices.first;
m_present_queue_family_index = queue_family_indices.second;
m_physical_device_name = props.properties.deviceName;
if (props.properties.deviceType == VK_PHYSICAL_DEVICE_TYPE_DISCRETE_GPU)
break; // If we find a discrete GPU, then prefer it
}
if (m_physical_device == VK_NULL_HANDLE)
{
printf("Failed to find a good physical device\n");
return false;
}
printf("Using physical device \"%s\"\n", m_physical_device_name.c_str());
return true;
}
void SampleVulkan::resize(uint32_t fb_width, uint32_t fb_height)
{
m_pending_swapchain_extent = {fb_width, fb_height};
m_swapchain_is_out_of_date = true;
}
bool SampleVulkan::create_device_and_swapchain()
{
const float priority = 1.0f;
std::vector<VkDeviceQueueCreateInfo> queue_create_infos;
// passing through std::set effectively dedups family indices.
// not really necessary to use std::set here as we only have to consider
// 2 families (graphics and present), so we could have just checked (family_index_1 == family_index_2),
// but this std::set approach generalizes to higher orders (imagine doing if/else checks for combinations of 3 or 4)
for (const auto index : std::set<uint32_t>{m_graphics_queue_family_index, m_present_queue_family_index})
queue_create_infos.push_back(VkDeviceQueueCreateInfo{
.sType = VK_STRUCTURE_TYPE_DEVICE_QUEUE_CREATE_INFO,
.queueFamilyIndex = index,
.queueCount = 1,
.pQueuePriorities = &priority,
});
std::vector<const char *> device_extensions{SWAPCHAIN_DEVICE_EXTENSION_NAME};
// macOS support: if the device is a portability implementation (i.e. MoltenVK),
// it exposes VK_KHR_portability_subset, and the spec requires us to enable it.
const auto device_ext_props =
vkEnumCall<VkExtensionProperties>(vkEnumerateDeviceExtensionProperties, m_physical_device, nullptr);
if (std::any_of(device_ext_props.begin(), device_ext_props.end(), [](VkExtensionProperties p) {
return strcmp(p.extensionName, PORTABILITY_SUBSET_DEVICE_EXTENSION_NAME) == 0;
}))
device_extensions.push_back(PORTABILITY_SUBSET_DEVICE_EXTENSION_NAME);
VkPhysicalDeviceFeatures enabled_features{};
VkPhysicalDeviceVulkan13Features vk_13_features{
.sType = VK_STRUCTURE_TYPE_PHYSICAL_DEVICE_VULKAN_1_3_FEATURES,
.synchronization2 = VK_TRUE,
.dynamicRendering = VK_TRUE,
};
VkDeviceCreateInfo device_create_info{
.sType = VK_STRUCTURE_TYPE_DEVICE_CREATE_INFO,
.pNext = &vk_13_features,
.queueCreateInfoCount = (uint32_t) queue_create_infos.size(),
.pQueueCreateInfos = queue_create_infos.data(),
.enabledLayerCount = 0,
.ppEnabledLayerNames = nullptr,
.enabledExtensionCount = (uint32_t) device_extensions.size(),
.ppEnabledExtensionNames = device_extensions.data(),
.pEnabledFeatures = &enabled_features,
};
if (vkCreateDevice(m_physical_device, &device_create_info, nullptr, &m_device) != VK_SUCCESS)
{
printf("Failed to create Vulkan device\n");
return false;
}
vkGetDeviceQueue(m_device, m_graphics_queue_family_index, 0, &m_graphics_queue);
vkGetDeviceQueue(m_device, m_present_queue_family_index, 0, &m_present_queue);
VmaAllocatorCreateInfo vma_create_info{
.physicalDevice = m_physical_device,
.device = m_device,
.instance = m_instance,
.vulkanApiVersion = VK_API_VERSION_1_3,
};
if (vmaCreateAllocator(&vma_create_info, &m_allocator) != VK_SUCCESS) {
printf("Failed to create the VMA allocator\n");
return false;
}
{
VkCommandPoolCreateInfo pool_create_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_POOL_CREATE_INFO,
.flags = VK_COMMAND_POOL_CREATE_RESET_COMMAND_BUFFER_BIT,
.queueFamilyIndex = m_graphics_queue_family_index,
};
if (vkCreateCommandPool(m_device, &pool_create_info, nullptr, &m_single_shot_command_pool) != VK_SUCCESS) {
printf("Failed to create the single shot command pool\n");
return false;
}
VkFenceCreateInfo fence_create_info{
.sType = VK_STRUCTURE_TYPE_FENCE_CREATE_INFO,
};
if (vkCreateFence(m_device, &fence_create_info, nullptr, &m_single_shot_command_fence) != VK_SUCCESS) {
printf("Failed to create the single shot fence\n");
return false;
}
VkCommandBufferAllocateInfo alloc_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_BUFFER_ALLOCATE_INFO,
.commandPool = m_single_shot_command_pool,
.level = VK_COMMAND_BUFFER_LEVEL_PRIMARY,
.commandBufferCount = 1,
};
if (vkAllocateCommandBuffers(m_device, &alloc_info, &m_single_shot_command_buffer) != VK_SUCCESS) {
printf("Failed to allocate the single shot command buffer\n");
return false;
}
}
const auto surface_formats =
vkEnumCall<VkSurfaceFormatKHR>(vkGetPhysicalDeviceSurfaceFormatsKHR, m_physical_device, m_surface);
const auto surface_present_modes =
vkEnumCall<VkPresentModeKHR>(vkGetPhysicalDeviceSurfacePresentModesKHR, m_physical_device, m_surface);
assert(surface_formats.size());
assert(surface_present_modes.size());
m_swapchain_format = surface_formats[0];
m_swapchain_present_mode = (std::find(surface_present_modes.begin(), surface_present_modes.end(),
VK_PRESENT_MODE_MAILBOX_KHR) != surface_present_modes.end())
? VK_PRESENT_MODE_MAILBOX_KHR
: VK_PRESENT_MODE_FIFO_KHR;
return recreate_swapchain();
}
bool SampleVulkan::create_frame_resources()
{
VkCommandPoolCreateInfo commmand_pool_create_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_POOL_CREATE_INFO,
.flags = VK_COMMAND_POOL_CREATE_RESET_COMMAND_BUFFER_BIT,
.queueFamilyIndex = m_graphics_queue_family_index,
};
if (vkCreateCommandPool(m_device, &commmand_pool_create_info, nullptr, &m_frame_resource_command_pool) != VK_SUCCESS)
{
printf("Failed to create command pool\n");
return false;
}
VkCommandBufferAllocateInfo command_buffer_alloc_info{
.sType = VK_STRUCTURE_TYPE_COMMAND_BUFFER_ALLOCATE_INFO,
.commandPool = m_frame_resource_command_pool,
.level = VK_COMMAND_BUFFER_LEVEL_PRIMARY,
.commandBufferCount = 1,
};
for (uint32_t i = 0; i < NUM_CONCURRENT_FRAMES; i++)
{
if (vkAllocateCommandBuffers(m_device, &command_buffer_alloc_info, &m_frames[i].cmd_buffer) != VK_SUCCESS)
{
printf("Failed to allocate frame command buffer\n");
return false;
}
VkSemaphoreCreateInfo semaphore_create_info{
.sType = VK_STRUCTURE_TYPE_SEMAPHORE_CREATE_INFO,
};
if (vkCreateSemaphore(m_device, &semaphore_create_info, nullptr, &m_frames[i].sm_image_available) != VK_SUCCESS)
{
printf("Failed to create a semaphore\n");
return false;
}
VkFenceCreateInfo fence_create_info{
.sType = VK_STRUCTURE_TYPE_FENCE_CREATE_INFO,
.flags = VK_FENCE_CREATE_SIGNALED_BIT,
};
if (vkCreateFence(m_device, &fence_create_info, nullptr, &m_frames[i].fen_in_flight) != VK_SUCCESS)
{
printf("Failed to create a fence\n");
return false;
}
}
return true;
}
bool SampleVulkan::recreate_swapchain()
{
vkDeviceWaitIdle(m_device);
VkSurfaceCapabilitiesKHR surface_caps{};
if (vkGetPhysicalDeviceSurfaceCapabilitiesKHR(m_physical_device, m_surface, &surface_caps) != VK_SUCCESS)
{
printf("Failed to query physical device surface caps\n");
return false;
}
// A minimized window has a 0x0 surface, and a 0x0 swapchain is not allowed. So we
// keep the current swapchain, and try again later (once the window is restored).
if ((surface_caps.maxImageExtent.width == 0) || (surface_caps.maxImageExtent.height == 0))
{
m_swapchain_is_out_of_date = true;
return true;
}
m_swapchain_image_count = std::min(surface_caps.minImageCount + 1,
(surface_caps.maxImageCount == 0) ? UINT32_MAX : surface_caps.maxImageCount);
m_swapchain_pre_transform = surface_caps.currentTransform;
m_pending_swapchain_extent.width = std::clamp(m_pending_swapchain_extent.width, surface_caps.minImageExtent.width,
surface_caps.maxImageExtent.width);
m_pending_swapchain_extent.height = std::clamp(m_pending_swapchain_extent.height, surface_caps.minImageExtent.height,
surface_caps.maxImageExtent.height);
m_swapchain_extent = m_pending_swapchain_extent;
m_depth_attachment.reset();
for (const auto &view : m_swapchain_image_views)
vkDestroyImageView(m_device, view, nullptr);
if (m_swapchain)
vkDestroySwapchainKHR(m_device, m_swapchain, nullptr);
m_swapchain_image_views.clear();
m_swapchain = VK_NULL_HANDLE;
VkSwapchainCreateInfoKHR swapchain_create_info{
.sType = VK_STRUCTURE_TYPE_SWAPCHAIN_CREATE_INFO_KHR,
.surface = m_surface,
.minImageCount = m_swapchain_image_count,
.imageFormat = m_swapchain_format.format,
.imageColorSpace = m_swapchain_format.colorSpace,
.imageExtent = m_swapchain_extent,
.imageArrayLayers = 1,
.imageUsage = VK_IMAGE_USAGE_COLOR_ATTACHMENT_BIT,
.imageSharingMode = VK_SHARING_MODE_EXCLUSIVE,
.preTransform = m_swapchain_pre_transform,
.compositeAlpha = VK_COMPOSITE_ALPHA_OPAQUE_BIT_KHR,
.presentMode = m_swapchain_present_mode,
.clipped = VK_TRUE,
};
uint32_t queue_family_indices[] = {m_graphics_queue_family_index, m_present_queue_family_index};
if (m_graphics_queue_family_index != m_present_queue_family_index)
{
swapchain_create_info.imageSharingMode = VK_SHARING_MODE_CONCURRENT;
swapchain_create_info.queueFamilyIndexCount = 2;
swapchain_create_info.pQueueFamilyIndices = queue_family_indices;
}
if (vkCreateSwapchainKHR(m_device, &swapchain_create_info, nullptr, &m_swapchain) != VK_SUCCESS)
{
printf("Failed to create swapchain\n");
return false;
}
m_swapchain_images = vkEnumCall<VkImage>(vkGetSwapchainImagesKHR, m_device, m_swapchain);
// Note that we use the *actual* number of images here, which can be
// more than the minImageCount we asked for.
for (auto semaphore : m_render_done_semaphores)
vkDestroySemaphore(m_device, semaphore, nullptr);
m_render_done_semaphores.assign(m_swapchain_images.size(), VK_NULL_HANDLE);
VkSemaphoreCreateInfo semaphore_create_info{
.sType = VK_STRUCTURE_TYPE_SEMAPHORE_CREATE_INFO,
};
for (auto &semaphore : m_render_done_semaphores)
{
if (vkCreateSemaphore(m_device, &semaphore_create_info, nullptr, &semaphore) != VK_SUCCESS)
{
printf("Failed to create a semaphore\n");
return false;
}
}
m_swapchain_image_views.reserve(m_swapchain_images.size());
for (const auto &image : m_swapchain_images)
{
VkImageViewCreateInfo create_info{
.sType = VK_STRUCTURE_TYPE_IMAGE_VIEW_CREATE_INFO,
.image = image,
.viewType = VK_IMAGE_VIEW_TYPE_2D,
.format = m_swapchain_format.format,
.components =
{
.r = VK_COMPONENT_SWIZZLE_IDENTITY,
.g = VK_COMPONENT_SWIZZLE_IDENTITY,
.b = VK_COMPONENT_SWIZZLE_IDENTITY,
.a = VK_COMPONENT_SWIZZLE_IDENTITY,
},
.subresourceRange =
{
.aspectMask = VK_IMAGE_ASPECT_COLOR_BIT,
.baseMipLevel = 0,
.levelCount = 1,
.baseArrayLayer = 0,
.layerCount = 1,
},
};
VkImageView view{};
if (vkCreateImageView(m_device, &create_info, nullptr, &view) != VK_SUCCESS)
{
printf("Failed to create a swapchain image view\n");
return false;
}
m_swapchain_image_views.push_back(view);
}
CHECK_RESULT(
Image::create(
m_device,
m_allocator,
VK_FORMAT_D32_SFLOAT,
m_swapchain_extent,
VK_IMAGE_USAGE_DEPTH_STENCIL_ATTACHMENT_BIT
),
m_depth_attachment
);
if (!execute_single_shot_commands([&](VkCommandBuffer cmd) -> Result<>
{
if (!m_depth_attachment->transition_layout(cmd, VK_IMAGE_LAYOUT_DEPTH_ATTACHMENT_OPTIMAL))
return "Failed to transition depth image layout";
return Ok();
})
)
return false;
g_vertex_uniform_data.projection = glm::perspective(glm::half_pi<float>(), (float)m_swapchain_extent.width/(float)m_swapchain_extent.height, 0.1f, 1.0f);
g_vertex_uniform_data.projection[1][1] *= -1.0f;
m_swapchain_is_out_of_date = false;
return true;
}Show main.cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#include "sample.hpp"

class SampleApp
{
  static constexpr uint32_t SCREEN_WIDTH = 800;
  static constexpr uint32_t SCREEN_HEIGHT = 600;

  public:
  int launch(int argc, char *argv[]);

  ~SampleApp();

  private:
  GLFWwindow *m_window{};
  Box<SampleVulkan> m_vulkan{};
};

int main(int argc, char *argv[])
{
  SampleApp app;
  return app.launch(argc, argv);
}

int SampleApp::launch(int argc, char *argv[])
{
  if (!glfwInit())
  {
    printf("Failed to initialize GLFW\n");
    return -1;
  }

  glfwWindowHint(GLFW_CLIENT_API, GLFW_NO_API);
  m_window = glfwCreateWindow(SCREEN_WIDTH, SCREEN_HEIGHT, "i-a-s.me Vulkan Sample", nullptr, nullptr);
  if (!m_window)
  {
    printf("Failed to create GLFW window\n");
    return -1;
  }

  m_vulkan = Box<SampleVulkan>(new SampleVulkan());
  if (!m_vulkan->initialize([window = m_window](VkInstance instance, uint32_t &out_width, uint32_t &out_height,
                                                VkSurfaceKHR &out_surface) -> bool {
        if (glfwCreateWindowSurface(instance, window, nullptr, &out_surface) != VK_SUCCESS)
        {
          printf("Failed to create Vulkan surface\n");
          return false;
        }

        int32_t fb_width{}, fb_height{};
        glfwGetFramebufferSize(window, &fb_width, &fb_height);
        while ((fb_width == 0) || (fb_height == 0))
        {
          glfwWaitEvents();
          glfwGetFramebufferSize(window, &fb_width, &fb_height);
        }

        out_width = (uint32_t) fb_width;
        out_height = (uint32_t) fb_height;

        return true;
      }))
  {
    printf("Failed to initialize Vulkan\n");
    return -1;
  }

  glfwSetWindowUserPointer(m_window, m_vulkan.get());

  glfwSetFramebufferSizeCallback(m_window, [](GLFWwindow *window, int width, int height) {
    int32_t fb_width{}, fb_height{};
    glfwGetFramebufferSize(window, &fb_width, &fb_height);
    if ((fb_width == 0) || (fb_height == 0))
      return;
    static_cast<SampleVulkan *>(glfwGetWindowUserPointer(window))->resize(fb_width, fb_height);
  });

  while (!glfwWindowShouldClose(m_window))
  {
    if (glfwGetKey(m_window, GLFW_KEY_ESCAPE))
      glfwSetWindowShouldClose(m_window, true);

    glfwPollEvents();

    // Don't render while the window is minimized (its framebuffer is 0x0 then)
    int32_t fb_width{}, fb_height{};
    glfwGetFramebufferSize(m_window, &fb_width, &fb_height);
    if ((fb_width == 0) || (fb_height == 0))
    {
      glfwWaitEvents();
      continue;
    }

    if (!m_vulkan->render())
      break;
  }

  return 0;
}

SampleApp::~SampleApp()
{
  m_vulkan.reset();

  if (m_window)
    glfwDestroyWindow(m_window);

  glfwTerminate();
}
Show vma.cpp
// Released into the public domain.
// Written by I-A-S for use in i-a-s.me vulkan series.

#define VMA_IMPLEMENTATION
#include <vk_mem_alloc.h>
Show shaders/default.vert
#version 450

layout(location = 0) in vec3 in_pos;
layout(location = 1) in vec3 in_color;
layout(location = 2) in vec2 in_texcord;

layout(std140, set = 0, binding = 0) uniform VertexUniformData {
    mat4 model;
    mat4 view;
    mat4 projection;
} uniform_data;

layout(location = 0) out vec3 out_color;
layout(location = 1) out vec2 out_texcoord;

void main() {
    gl_Position = uniform_data.projection * uniform_data.view * uniform_data.model * vec4(in_pos, 1.0);
    out_color = in_color;
    out_texcoord = in_texcord;
}
Show shaders/default.frag
#version 450

layout(location = 0) in vec3 in_color;
layout(location = 1) in vec2 in_texcoord;

layout(set = 1, binding = 0) uniform sampler2D texture_sampler;

layout(location = 0) out vec4 finalColor;

void main() {
    finalColor = texture(texture_sampler, in_texcoord);
}